If you’ve been to the start page of this site lately, you may have
noticed the ~elis/popular-posts/ section. It lists the blog posts that
people actually read, based on the last 90 days of traffic. It used to
be something I updated by hand every now and then, but now it refreshes
itself every Sunday night.
How the section works
The section is driven by a single front matter field, popularRank.
Any blog post that sets it is listed on the start page, sorted by the
rank:
They are an experimental-feature in Nix that lets a derivation produce other derivations as its output. Why ? This lets you dynamically create your build graph, instead of having to know it all at evaluation time. It’s Nix’s answer to try and match the build speed of other build systems like Bazel or buck2.
There is not much written about dynamic derivations, and the documentation is sparse. I have writtenafewposts about them, so I sometimes get questions about them.
Recently, I got a DM from Evan Porter over LinkedIn, the ultimate bug triaging network, about whether it is possible to query the deriver of a dynamic derivation to get the initial derivation.
For dynamic derivations let’s say I have a .drv.drv file. This file outputs a derivation.
Is it usually possible to query deriver the output derivation to obtain the initial derivation?
That should work. 🤨 Every path a build registers carries a deriver, the .drv that produced it, and a .drv that came out of a build is still a path a build registered.
When I tried it, it worked. 🤷
You will need extra-experimental-features = dynamic-derivations ca-derivations recursive-nix in your nix.conf to drive the samples in this post.
Turns out, there is a case where you do get unknown-deriver if you set __contentAddressed = true on the producer. If the producer is content-addressed, its output path is not known until after the build, and Nix does not fill in the deriver of a path that already exists.
I filed NixOS/nix#16823.
The question though made me wonder how far back you can walk the chain of dynamic derivations. I had to try it. 😈
Let’s pick a fun example to see how far we can go. Here is a derivation that imitates the classic song 99 bottles of beer by producing a chain of derivations, each one outputting the next verse.1
export PATH=$busybox/bin
# A content-addressed derivation does not know its output path, so its# "out" variable holds this placeholder and Nix swaps in the real path at# build time. It is "/" + nix32(sha256("nix-output:out")), the same for# every derivation with an output named "out".OUT_PLACEHOLDER=/1rz4g4znpzjwh1xymhjpm42vipw92pr73vdgl6xs1hycac8kf2n9
bottles(){case$1in
0)echo"no more bottles";;
1)echo"1 bottle";;*)echo"$1 bottles";;esac}# The last derivation in the chain writes the punchline instead of a .drv.if["$n"-eq 0 ];then
echo"No more bottles of beer on the wall, no more bottles of beer.">&2
echo"Go to the store and buy some more.">$outexit 0
fi
next=$((n -1))echo"$(bottles $n) of beer on the wall, $(bottles $n) of beer.">&2
echo"Take one down, pass it around, $(bottles $next) of beer on the wall.">&2
# Input sources must be sorted.srcs=$(printf'"%s"\n'"$busybox""$script" | sort | paste-sd, -)# Write the derivation for the next verse. A .drv is a single line of# ATerm, so strip the spaces and newlines that are only here for reading.# Nix takes a derivation's name from its store path, so the next name is# ours minus one ".drv".tr-d' \n'>$out<<EOF
Derive(
[("out", "", "text:sha256", "")],
[],
[$srcs],
"$system",
"$busybox/bin/sh",
["$script"],
[
("builder", "$busybox/bin/sh"),
("busybox", "$busybox"),
("n", "$next"),
("name", "${name%.drv}"),
("out", "$OUT_PLACEHOLDER"),
("outputHashAlgo", "sha256"),
("outputHashMode", "text"),
("script", "$script"),
("system", "$system")
]
)
EOF
Tip
A derivation whose output is a .drv must set outputHashMode = "text".
In our example we are using a content-addressed derivation, but the same idea works with an input-addressed one, but it’s more work to compute the output path in the shell, unless you are using nix-instantiate to do it for you with recursive Nix.
The Nix side builds the first derivation and then follows builtins.outputOf once per bottle.
letpkgs=import(fetchTarball{url="https://github.com/NixOS/nixpkgs/archive/6dadaf4375be35033e1c84395adbd53ff5fded96.tar.gz";}){};inherit(pkgs)lib;# maximum bottles of beer on the wall,# 50 is the most that fits in a store path!?bottles=50;top=derivation{name="beer"+lib.concatStrings(lib.replicatebottles".drv");system=builtins.currentSystem;builder="${pkgs.busybox}/bin/sh";args=[./bottles.sh];script=./bottles.sh;busybox=pkgs.busybox;n=bottles;__contentAddressed=true;outputHashMode="text";outputHashAlgo="sha256";};in# Follow the chain of outputs down to the last derivation.lib.foldl'(drv:_:builtins.outputOfdrv"out")top.outPath(lib.range1bottles)
While working through this example, I hit a bug in Nix that made me set __contentAddressed = true on the top derivation. That is not necessary for a derivation that outputs a .drv, but it works around the bug. I filed NixOS/nix#16830.
You might notice that we limit the number of beers to 50. Why 50 and not 99?
Well, 50 is the most that fits in a store path.
error: path '…-beer.drv.drv.drv…' is not a valid store path:
  name 'beer.drv.drv.drv…' must be no longer than 211 characters
The maximum length of a store path is 211 characters. A derivation’s store path must include the .drv suffix, and every .drv in a chain adds four characters. The top derivation is named beer and if you add 51 .drvs we get 208 characters. No room for any more beer. 🍻
Aside
Even with a name of length 1, , we get a theoretical limit of .
Let’s build sing it.
$nix build -f beer.nix \ --print-out-paths \
--print-build-logs
building '/nix/store/di5x9yrhh6pfn214c41bnpxh1avya51c-beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv'...
beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv>50 bottles of beer on the wall, 50 bottles of beer.
beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv>Take one down, pass it around, 49 bottles of beer on the wall.
building '/nix/store/zg35ykl6qvh6gasy6q4pc6d4kyqcq0sd-beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv'...
beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv>49 bottles of beer on the wall, 49 bottles of beer.
beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv>Take one down, pass it around, 48 bottles of beer on the wall.
building '/nix/store/g07drgnkmwkbyccwk8vzzibbfdznpqjd-beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv'...
beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv>48 bottles of beer on the wall, 48 bottles of beer.
beer.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv.drv>Take one down, pass it around, 47 bottles of beer on the wall.
...
building '/nix/store/0vr55qvmaswc2vkjvy4i2blcgc6phv85-beer.drv.drv'...
beer.drv>1 bottle of beer on the wall, 1 bottle of beer.
beer.drv>Take one down, pass it around, no more bottles of beer on the wall.
building '/nix/store/kb16larpavss7y26ivyib5mgc23gicn6-beer.drv'...
beer>No more bottles of beer on the wall, no more bottles of beer.
/nix/store/kp2aln1pr2cy4gn9qs8vzkq850blj60i-beer
$cat result
Go to the store and buy some more.
Fifty-one builds, one after another2. Evaluation knows about only the first one. Nix discovers each of the other 50 by building the one before it. 🍺
Aside
Hey, didn’t an earlier post have dynamic derivation chains 500 deep?!
Yes! The difference is whether a derivation outputs the next one or depends on it. A derivation whose output is another derivation gets one more .drv appended to the name. The dice chain linked each step to the next as a dependency, and a dependency keeps its own name, so no name ever had more than two .drvs in it.
Back to the original question: can we query the deriver of the output derivation to get the initial derivation? Yes, we can.
Let’s put nix-store --query --deriver in a loop that walks from the result all the way back to the top.
Since every derivation in the chain was built, every one has a build log, and you can ask any of them to sing its verse again.
$nix log "$(sed-n 26p chain.txt)"24 bottles of beer on the wall, 24 bottles of beer.
Take one down, pass it around, 23 bottles of beer on the wall.
I’m very excited for the future of dynamic derivations. tomberek is leading a working-group to finalize the feature and are currently meeting weekly. With dynamic derivations, Nix will be able to compete with other build systems in terms of speed and flexibility and take over the world.
The builder writes the next derivation by hand in ATerm, so there is no recursive Nix and no nix-instantiate involved. ↩
A single trivial build takes about 1.5 seconds on my laptop, so the cost of building 51 derivations is about 75 seconds largely due to substituter lookups. If you disable substituters --option substituters '', the builds take about 1.3 seconds in total. ↩
Okay, I am the first to admit that I’m a bit manic with AI. When you are working on a problem that has endless possibilities, it is difficult to constrain yourself to a limited set of features.
Turns out that performance is yet another area where Rewind shines. I have been using it to analyze the critical path of builds.
What is the critical path?
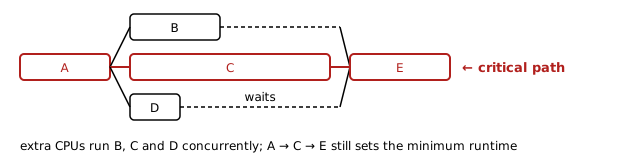
The critical path is the longest chain of dependent work in a program. It is the minimum time that the program can take to complete, regardless of how many resources you throw at it. The only way to make a program faster is to shorten the critical path.
If you worship at the altar of Brendan Gregg, you know he spent years turning performance analysis from a dark art into a science. This is a small offering to him. 🤲
I added a new rewind time command to Rewind that analyzes a recording and tells you where the time went and what would make the run finish sooner. You can drill into any part of that answer and see the source lines responsible for it. It’s like Brendan Gregg’s flame graphs but on steroids for the critical path and with a debugger attached.1
Let’s see how it works by analyzing the critical path of a libuv build and test run. The build and test suite takes 78 seconds inside Rewind, and even with 64 cores it still takes 47 seconds. Why?
The usual answer is to look at a CPU profile, and in this case a CPU profile would be almost useless. For two thirds of those 47 seconds, the work the build is waiting on is not computing at all: it is asleep. 💤💤💤
Where the time goes
Every rewind time starts with two numbers:
$rewind time 7a29e716
libuv-1.51.0
78.0 s elapsed on the VM's one CPU
47.4 s critical path: the least it can take on any number of CPUs
67% asleep (epoll_pwait 23.1 s, clock_nanosleep 8.53 s, futex 100 ms), 33% computing
The first is how long the run took on the VM’s one virtual CPU. The second is the critical path: the longest chain of work where each step had to wait for the one before.
No number of CPUs makes a run shorter than its critical path, so the gap between the two numbers is all that parallelism can buy you.
The line under the two numbers applies Gregg’s thread state analysis. Here the biggest state is asleep: 23 seconds in epoll_pwait and 8.5 in clock_nanosleep.
A sleeping thread is invisible to a CPU profiler. Gregg’s answer is off-CPU analysis: look at where threads block, not only where they compute.
On a live machine, off-CPU analysis is hard. Linux can trace which thread woke which, and Gregg built wakeup and off-wake profiling on top of that, but you have to be tracing before the slow run happens, the tracing has a cost, and most of the sleeps you capture are noise. Rewind already logs every context switch because it needs them to replay, and now it records every wakeup and who caused it too. All that juicy information is in every recording. 🤤
Here is the whole output for libuv:
$rewind time 7a29e716
libuv-1.51.0
78.0 s elapsed on the VM's one CPU
47.4 s critical path: the least it can take on any number of CPUs
67% asleep (epoll_pwait 23.1 s, clock_nanosleep 8.53 s, futex 100 ms), 33% computing
The critical path by phase
3.54 s configurePhase ██
1.67 s buildPhase █
42.0 s checkPhase █████████████████████
99 ms 5 other phases
The critical path by process
on path pid process, with what it started
47.4 s 34 init › bash -e source-stdenv.sh default-builder.sh
41.9 s 4076 ├─ make -j8 SHELL=bash-5.3p3/bin/bash VERBOSE=y check
36.4 s 4910 │ ├─ make › bash › lt-run-tests
3.38 s 5412 │ │ ├─ lt-run-tests hrtime hrtime asleep in clock_nanosleep 3.38 s
2.00 s 5013 │ │ ├─ lt-run-tests delayed_accept delayed_accept asleep in epoll_pwait 2.00 s
1.62 s 5126 │ │ ├─ lt-run-tests fs_event_watch_dir fs_event_watch_dir asleep in epoll_pwait 1.62 s
1.60 s 5103 │ │ ├─ lt-run-tests fs_event_close_in_callback fs_event_close_in… asleep in epoll_pwait 1.60 s
1.60 s 5508 │ │ ├─ lt-run-tests metrics_idle_time metrics_idle_time asleep in epoll_pwait 1.00 s, computing 600 ms
1.24 s 6095 │ │ ├─ lt-run-tests tcp_write_ready tcp_write_ready
1.14 s 5510 │ │ ├─ lt-run-tests metrics_idle_time_thread metrics_idle_time_t… asleep in epoll_pwait 1.00 s
1.10 s 5132 │ │ ├─ lt-run-tests fs_event_watch_file_current_dir fs_event_wat… asleep in epoll_pwait 1.10 s
22.6 s │ │ └─ 279 more
5.59 s 4077 │ └─ make test/run-tests
2.22 s 4183 │ ├─ gcc -fPIC -fstack-clash-protection -O2 -U_FORTIFY_SOURCE …
2.10 s 4189 │ │ └─ cc1 /build/source/test/test-fs.c
3.35 s │ └─ 20 more
1.99 s 68 ├─ sh ./autogen.sh
1.99 s │ └─ 9 more
1.67 s 2642 ├─ make -j8 SHELL=bash-5.3p3/bin/bash
1.67 s │ └─ 5 more
1.53 s 403 └─ bash ./configure --disable-static --disable-dependency-tracking…
1.47 s └─ 581 more
What would shorten it
sooner pid if this took no time
36.1 s every lt-run-tests, 600 processes
6.66 s every cc1, 283 processes
3.38 s 5412 75 sleeps in clock_nanosleep: lt-run-tests hrtime hrtime
2.00 s 5013 2 sleeps in epoll_pwait: lt-run-tests delayed_accept delayed_accept
1.76 s 4189 cc1 /build/source/test/test-fs.c
1.62 s 5126 30 sleeps in epoll_pwait: lt-run-tests fs_event_watch_dir fs_event_watc…
1.60 s 5103 16 sleeps in epoll_pwait: lt-run-tests fs_event_close_in_callback fs_ev…
1.60 s 5508 lt-run-tests metrics_idle_time metrics_idle_time
1.22 s every perl, 9 processes
1.14 s 5510 lt-run-tests metrics_idle_time_thread metrics_idle_time_thread
Look closer
rewind time 7a29e716 --in PID one process: its threads, sleeps and waits
rewind time 7a29e716 --folded the path for flamegraph.pl or speedscope.app
rewind time 7a29e716 --perfetto F every process on a timeline, for ui.perfetto.dev
The second table is the path as a tree of processes based on Gregg’s colony graph idea. Each line is a process with everything it started, and its time on the critical path.2
In this build, make check needs 41.9 of the total 47.4 seconds, and 36.4 of that is lt-run-tests, libuv’s test runner. The test runner invokes 287 tests each spending 1-3 seconds.
All of those tests are on the path, and the path is a single chain, so the runner ran them one after another. Worse, most of each test is spent asleep, waiting on timers.
Drag can be less than time on the path.
The last table answers a different question: how much sooner would the run finish if this part took no time? The critical path method calls this drag.
For the truly magical part, we can jump to any part of the path and see what was happening, invoke gdb and fork the run at that moment. A profiler hands you a stack, sampled at some moment you can never go back to. Every frame in rewind time is a moment in a recording, and Rewind can replay the run to it.
--in looks inside one process,3 so let’s dive into the hrtime test that spent 3.38 seconds asleep in clock_nanosleep:
$rewind time 7a29e716 --in hrtime
lt-run-tests hrtime hrtime (pid 5412)
3.38 s on the critical path with what it started, 7% of the 47.4 s path
100% asleep (clock_nanosleep 3.38 s), <1% computing
What would shorten it
sooner pid if this took no time
3.38 s 75 sleeps in clock_nanosleep
Look closer
rewind where 7a29e716 115894 --pid 5412 the source line the first row's time starts at
rewind time 7a29e716 --perfetto F every process on a timeline
Since this test spent 100% of its time asleep, the step provided on the last line is where it began. rewind where replays the run to that step and asks gdb where the thread was:
$rewind where 7a29e716 115894 --pid 5412
process 5412 (lt-run-tests), thread 5412, at step 115894
#2 uv_sleep (src/unix/core.c:1869) 1867
1868 do
>1869 rc = nanosleep(&timeout, &timeout); 1870 while (rc == -1 && errno == EINTR); 1871
arguments:
msec = 45
locals:
timeout = {tv_sec = 0, tv_nsec = 45000000}
rc = <optimized out> __PRETTY_FUNCTION__ = <error: Cannot access memory at address 0x7fb172519ae8>called from #3 run_test_hrtime (test/test-hrtime.c:39)called from #4 __libc_start_call_main (../sysdeps/nptl/libc_start_call_main.h:58)
🎯 We can see that the test is calling uv_sleep(45) from line 39 of test/test-hrtime.c, and that it is sleeping for 45 milliseconds.
It does that 75 times for a total of 3.38 seconds.4
As the cherry on top: the run is deterministic, so step 115,894 is the same instruction every time you replay it. You can open rewind gdb at that step and investigate to your heart’s content.
The Rewind app’s Time tab shows the same answers. The path becomes a flame graph, colored the way Gregg colors his off-CPU flame graphs: computing is warm, asleep is blue, and a process shades from one to the other by how much of its time it slept.
Clicking a frame picks it and moves the playhead there, so the build log, the process tree and the files all show that moment; clicking a process again zooms into it. When you pick a blue frame, the app replays the run to that part’s longest sleep and shows the stack where it slept:
Under the stack, Show source opens the source panel at that moment on that thread, and Open gdb here opens gdb in a fork of the run at the sleep:
If you’d rather use tools you already know, rewind time can emit the data in their formats: folded stacks for flamegraph.pl and speedscope, or a Perfetto trace for ui.perfetto.dev.
The flame graph below is the real flamegraph.pl output: click a frame to zoom in, or open it on its own.
Kneeling at the altar
Every idea here predates Rewind. Gregg has been drawing off-CPU and wakeup flame graphs for over a decade, and build systems have reported critical path information potentially even longer.5 I have been inspired by his work since I first dabbled in eBPF, back when flame graphs were new. 🙇
What Rewind adds is the data. Lots of it.
Rewind has that data because it can’t replay without it. On a single CPU the only thing that changes from run to run is the scheduler, so every recording already logs every context switch.
This changes the economics of performance analysis. On a live machine, you have to trace before the run, and tracing has a cost. You can only trace a few runs, and you have to pick which ones. Rewind traces every run, so you can analyze any of them later, and do so exactly.
It has just been a manic fever joy to take ideas I have admired for years, point them at a deterministic VM, and watch them work in ways that are hard or impossible on a normal machine.
Please accept rewind time as my offering at the altar of Brendan Gregg.
All the ideas for the command are either inspired by or directly influenced by Brendan Gregg’s work. Kneel before Zod! ↩
A ps snapshot might miss short-lived process invocations; the recording has every fork, regardless of how brief. ↩
It can take a pid, a program or a word of the command line. ↩
Turns out that the test sleeps on purpose: it is checking how far uv_hrtime moves across a sleep. There is nothing to optimize in this case. ↩
The security take-off is here, and the answer isn't more AI. It's engineering. I gave a talk at AI DevCon New York about patching the planet with Nix and agents, how I got through the last round of security incidents without losing any sleep, and a bonus round on loops, back pressure and property-based testing.
Everyone at the conference spent two days hearing about how to build software faster with factories. Cool. I wanted to talk about something different: how do you respond to security incidents faster? It turns out that if you optimise for incident response times, your build times speed up too. Here's the talk, written up properly, with the slides broken out and chapter links at the bottom if you want to jump to a specific part.
It turns out the answer for AI is engineering.
two weeks ago was pretty wild, huh?
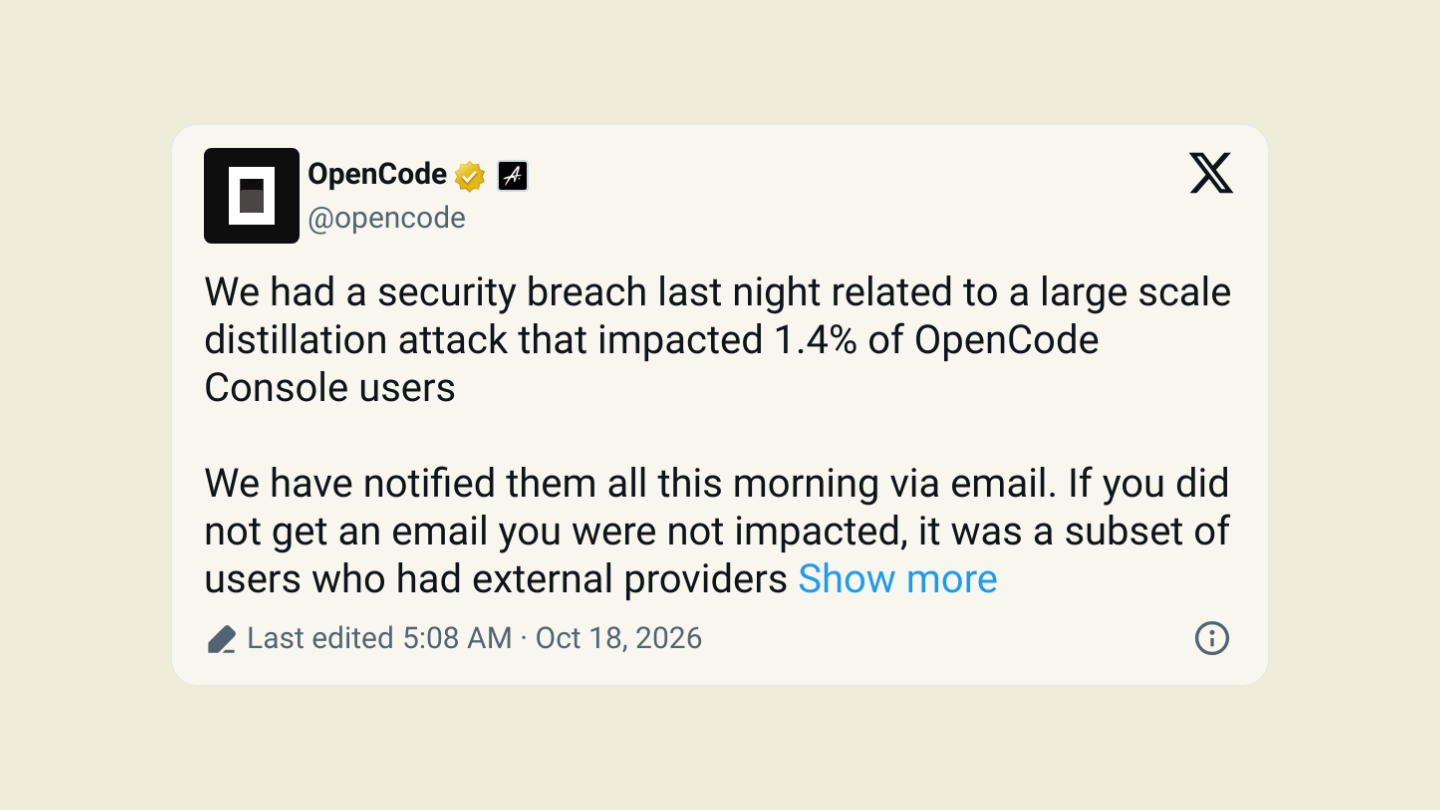
OpenCode got breached. Then the Prime Minister of Japan was tweeting at everyone to go and update PHP.
Next thing you know, there's a vulnerability in an HTTP stack that lets anyone remotely turn off a running server. Then a 12-year-old GitLab flaw that led to remote code execution on self-managed servers. Ouch.
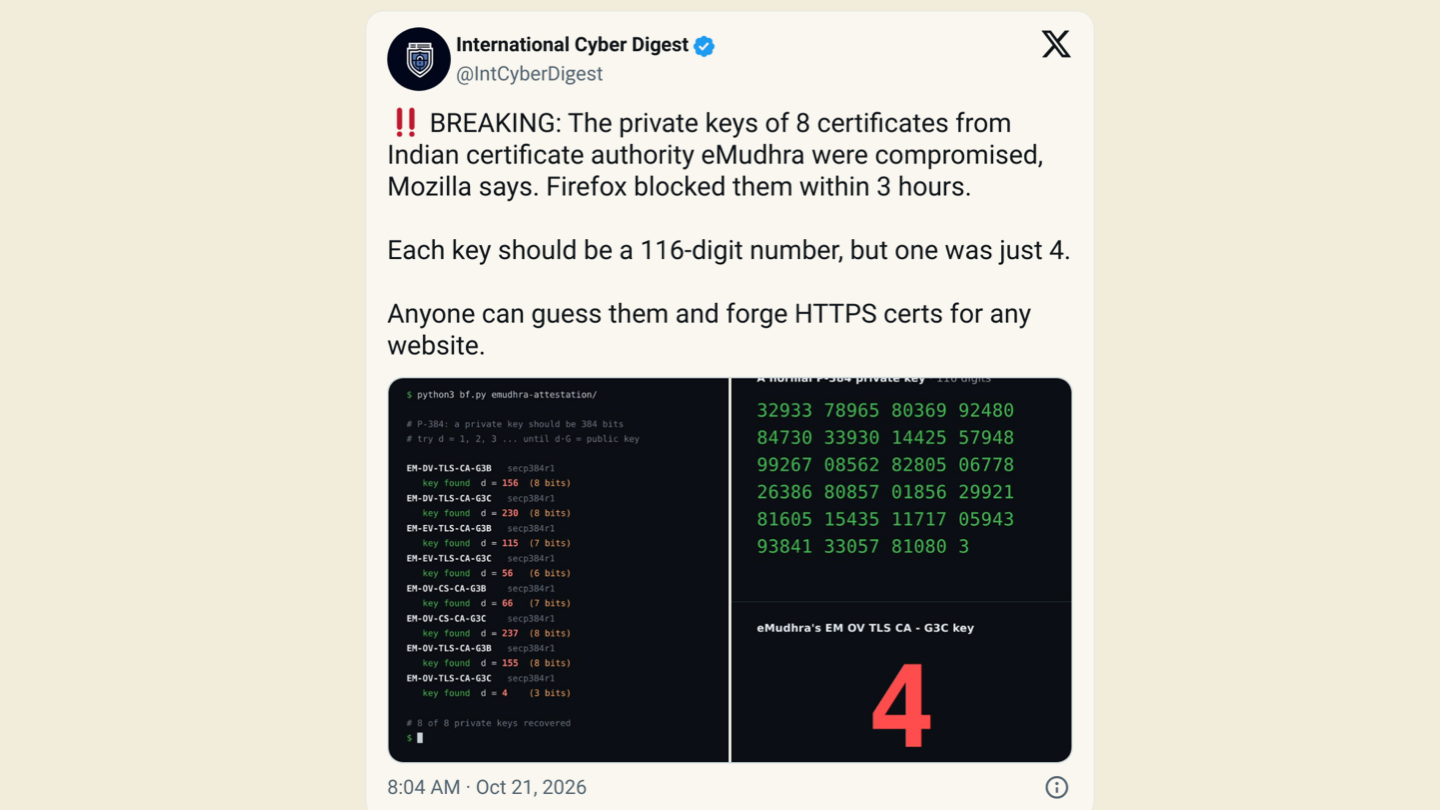
And it turns out the answer to life, the universe, and everything isn't 42. It's 4. A certificate authority had a key that should have been a 116-digit number, and it was just 4. Anyone who could guess it could forge HTTPS certificates for any website.
The number 4 opens all doors on the internet.
So we started wondering: is it time to turn the internet off yet?
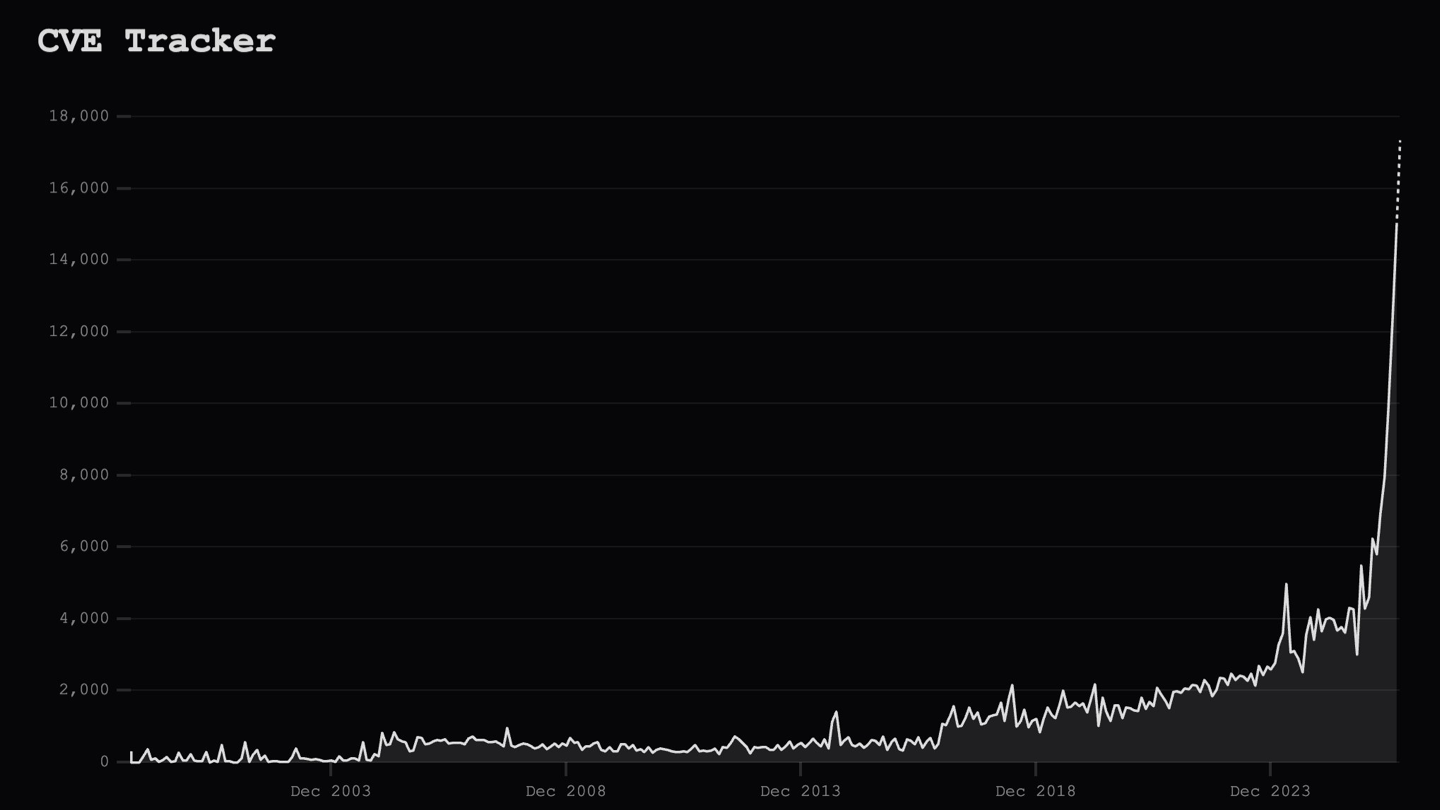
You've probably seen the graph of GitHub pull requests going quadratic, and GitHub having availability issues because of it. That's agent take-off. Below is the security version of that: the security take-off.
I'm putting it to you that this is the start of the new normal. You could argue it's a bump in the road, and once all the software has been patched, things will calm down. Maybe. But agents are writing software now; agents were trained on existing code, and existing code is full of these vulnerabilities.
you'll need more inferencing than your attackers
Unfortunately, cyber is only going to accelerate from here. It's going to get really weird, because I suspect you're going to need more inferencing capacity than your attackers to stay secure.
Think about the companies right now saying, "oh no, we can only do a $100-a-month token budget per employee." Yeah, no. As soon as you publish any code on GitHub, someone with racks of inferencing hardware will autonomously scan it and then autonomously make tool calls to exploit what they find. That's the new state of normal.
why do we have open-source dependencies?
Almost a year ago I wrote a blog post asking why we even have open-source libraries. I got grilled to hell on Hacker News for it, but every day that goes by it becomes more true.
We had open-source libraries because code was precious. It was hard to write, so we concentrated it into libraries to make reuse easy. We also did it to make hiring easier: React was famously a play by Facebook to standardise frontend development so they could hire for it. We optimised our practices for humans, and I don't think we need libraries anymore.
I'm not saying you should go and vibe-code your own cryptography. If you're a cryptographer, please do. I'm not. There's still going to be a trusted base and a trusted core. But think about your supply chain. How much time do you spend on Dependabot updates? How much time do you spend on incident response because a Dependabot update was compromised, because the upstream author was compromised? We're already losing time, all because the prior was that writing software was hard.
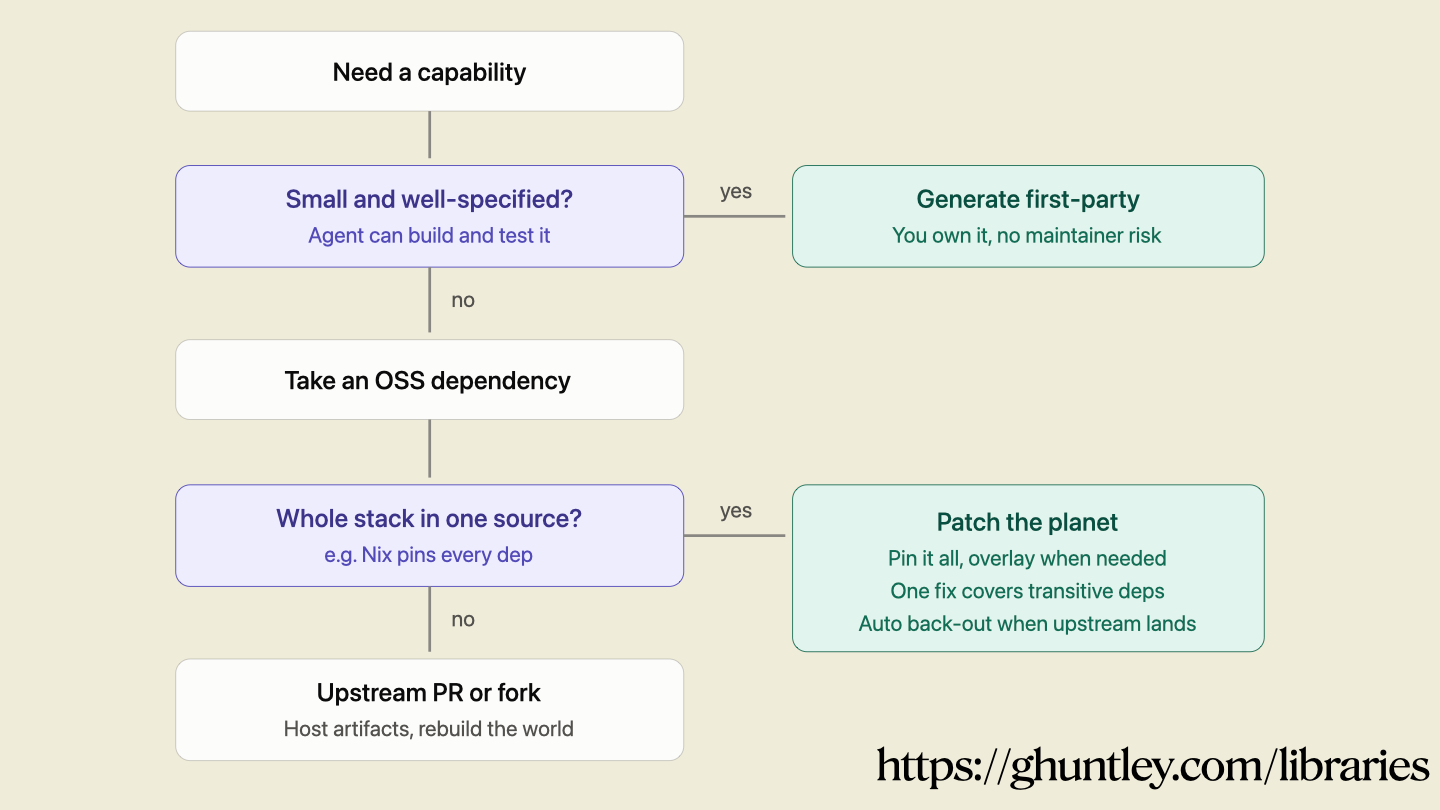
It's been a year, and I don't use much open source anymore. Sure, I use the Linux kernel, DNS servers like BIND, and the lower-level stuff. But once I get into higher-level code, I just prompt the agent for what I want. It feels very unnatural at first. If it's small and well-specified, like a command-line argument parser, you could take that dependency, or you could have Claude build it in a loop.
Something magical happens when you do: it's built for your use case, and you don't need to get someone on GitHub to merge your pull request. It turns out that if you have to tool call a human, that's not AGI.
So the best you can do is either generate it first-party, or vendor the open-source software and check it into your repo so the agent can modify and extend it. That's one approach. Today I want to show you a different one.
I'm calling it patch the planet. Patching is perceived to be hard, but it doesn't have to be. What makes it hard? Say you want to patch something on GitHub. You have to figure out how that software builds, learn its toolchain, and set up a new CI job just for that one thing. You do that per language, and every open-source library has a different build toolchain. Then once you've patched it, you need to host it in an artifact repo, and now you're thinking about artifact tokens. We make things needlessly complex.
There's been a solution for a long time: Nix. It's been around since 2003, and I've used it for years. You might have heard that Nix sucks. It does. There's no silver bullet. The most common complaint is that it's hard to use. It was. Agents know how to drive towards an outcome, so you just need to know that Nix exists, then prompt the agent: I want Nix here. The same goes for Bazel and Buck2. Talk to any eng leader, and they've got a story about nearly getting fired after staffing a team of five to introduce one of these, and then spending forever upskilling every developer. That's no longer true. You can now use highly complex, high-powered tools simply. You just have to know they exist, and you have to falsify your priors.
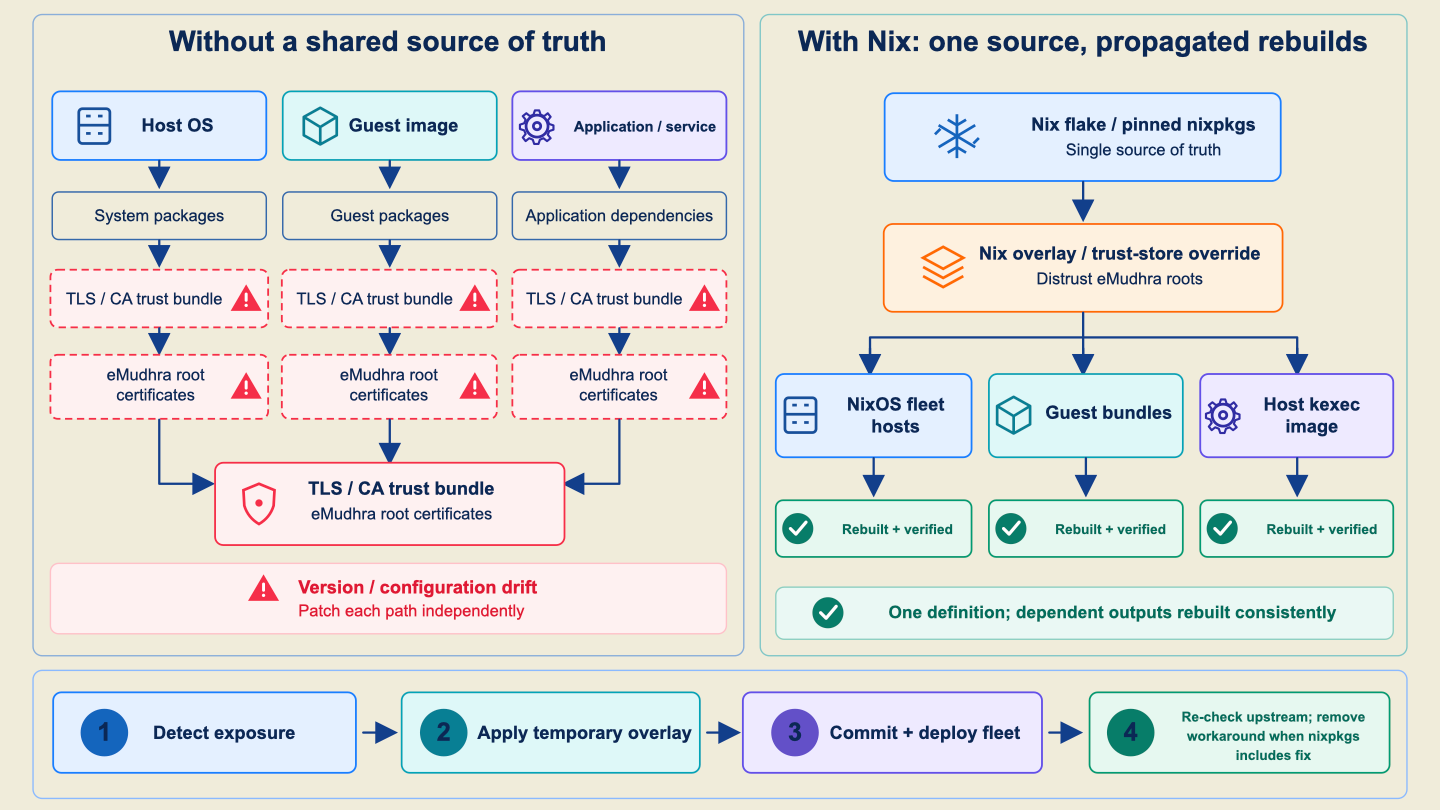
one source of truth
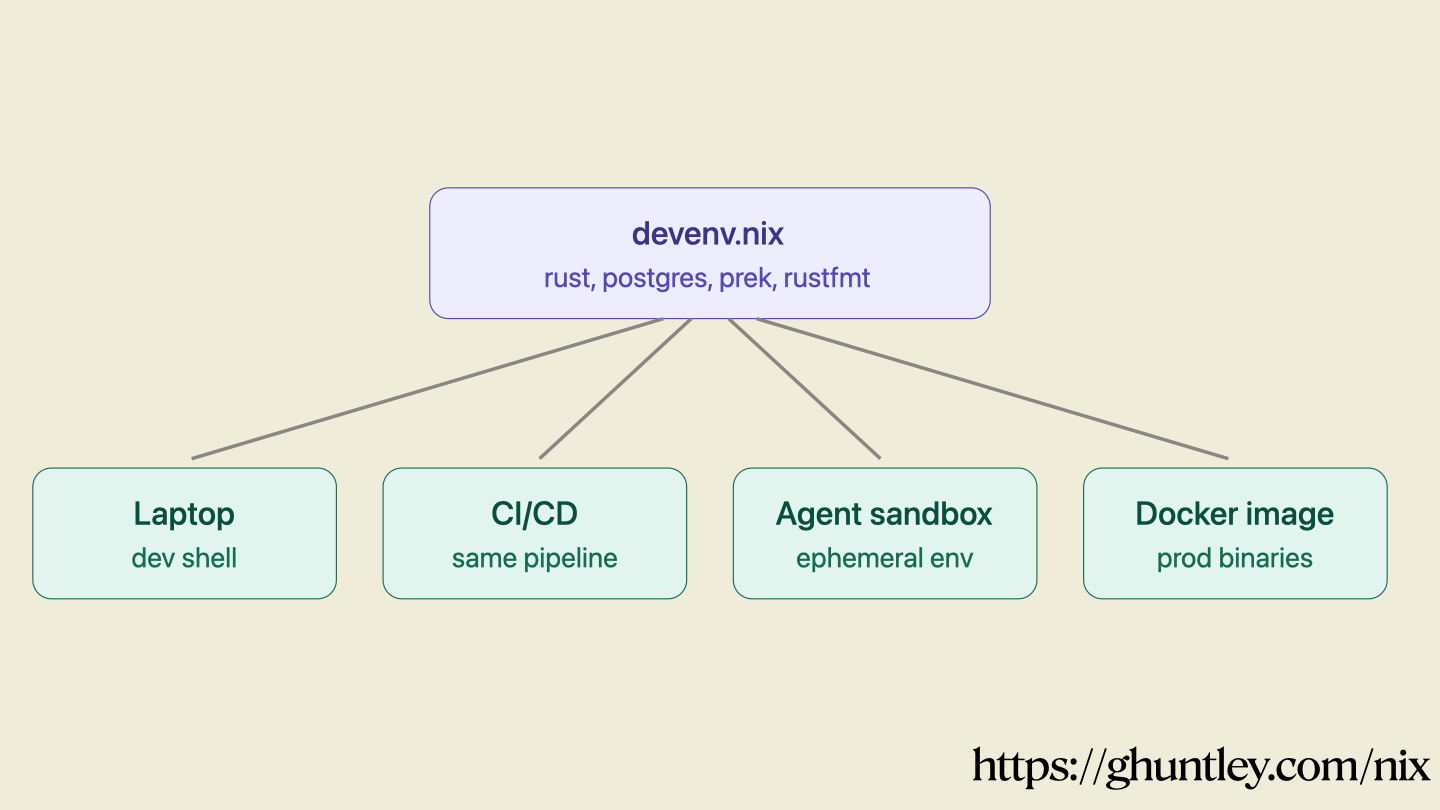
The demo is up on my GitHub as nix-demo below. Clone it down and have a look, because there are some interesting things in there. I use devenv, which is a nice gentle introduction to Nix. You define your packages and services in Nix, and that one file generates your developer laptops, your CI/CD, your agent sandboxes and your production Docker images.
See where I'm going? A single source of truth. How many people are spinning up teams right now to figure out agent sandboxes, and are they just duplicating environments? I'd bet that at some of your companies the laptop setup isn't reproducible: onboard a new employee or lose a laptop, and it's 48 hours to rebuild the developer environment. Then there's drift in CI/CD, so it works on your computer but CI says it doesn't. The agent sandbox is another source of drift. And finally, you say it's all done, but your software increment doesn't work in the production Docker image.
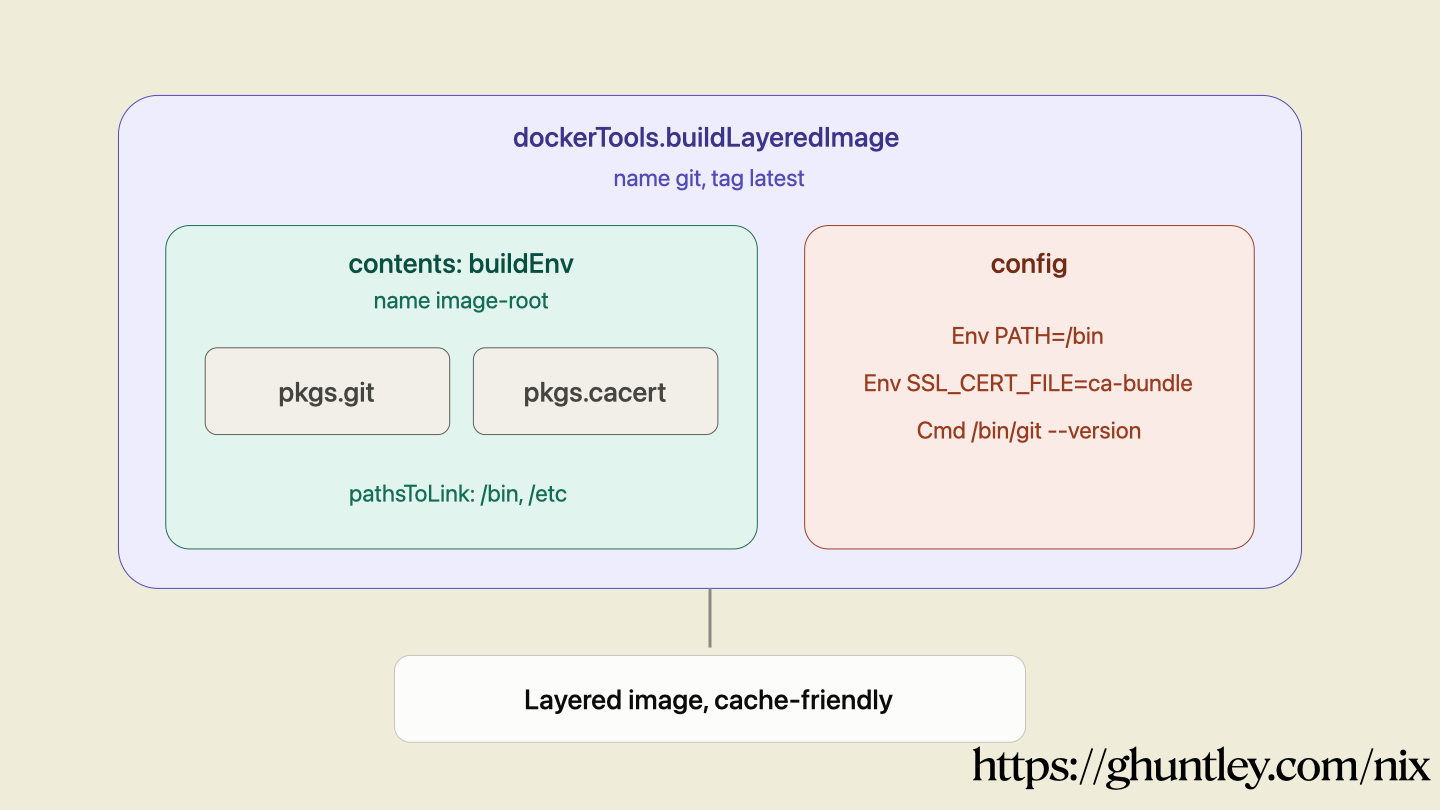
Interestingly, the Docker images Nix produces are incredibly efficient. Docker basically stacks file-system layers on top of each other and squashes them. Nix is a graph, and it uses that graph to build a very optimised image.
Imagine I'm a new engineer with a brand new computer, onboarding into the company; all I need to do is change my working directory to the source code checkout.
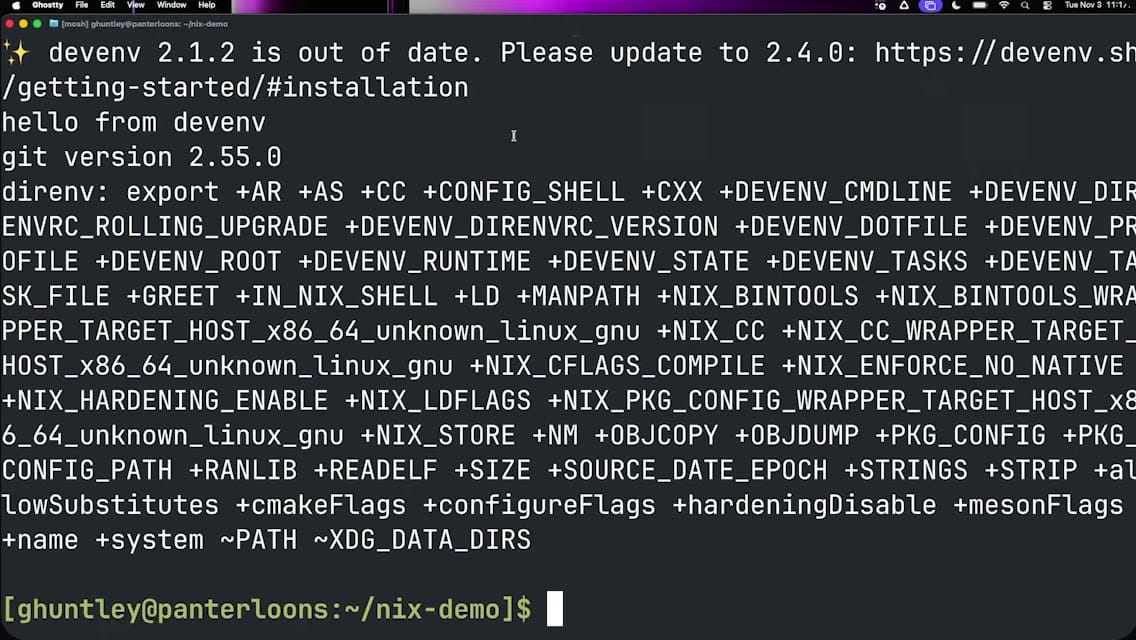
My globally installed git is 2.54, but I cd into the project, and I'm onboarded.
Think nvm or a Python version manager, but for all of your operating-system dependencies, including across the FFI boundaries; it goes past the programming language.
After changing my working directory git is 2.55. What's so special about this version of git? It's not just a newer version.
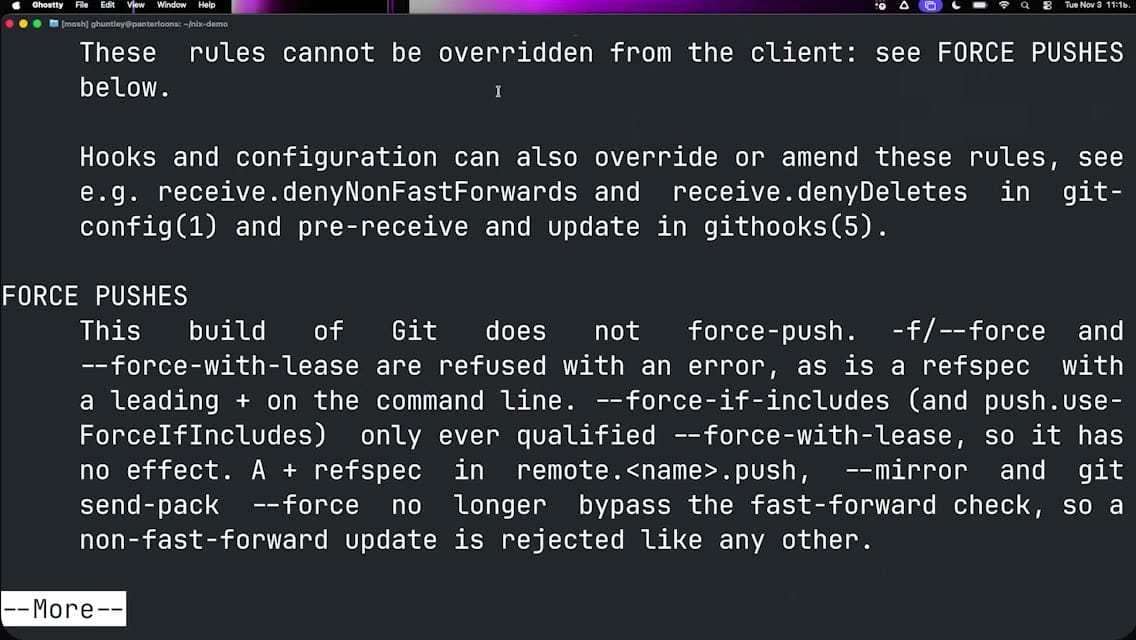
This version of git doesn't support force push. I've monkey-patched it for my agent sandboxes, my local engineering laptops, and everywhere else I use git. It's a single source of git, so anything that needs git as a transitive dependency also gets my patched version.
The best way to stop a model from doing something is to remove its ability to do it.
How do you stop an agent from force pushing? It hill-climbs toward its goal and does destructive things along the way. When that causes incidents, remove the capability from the underlying system. I use this trick all over the place, and sometimes the best way is to monkey-patch the system underneath.
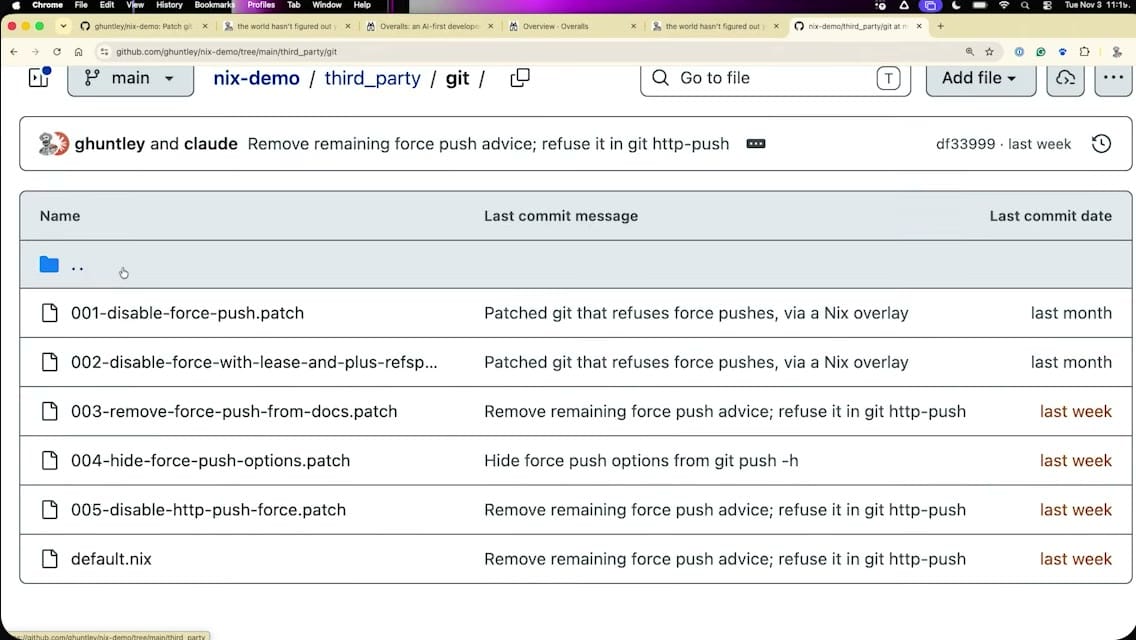
Those of you from my generation will remember patch files. Open source used to be distributed as a collection of patch files. The idea that everything must be merged upstream on GitHub was never part of open source. This is how we used to do software development. Here I have a closure that defines git, plus my custom patches.
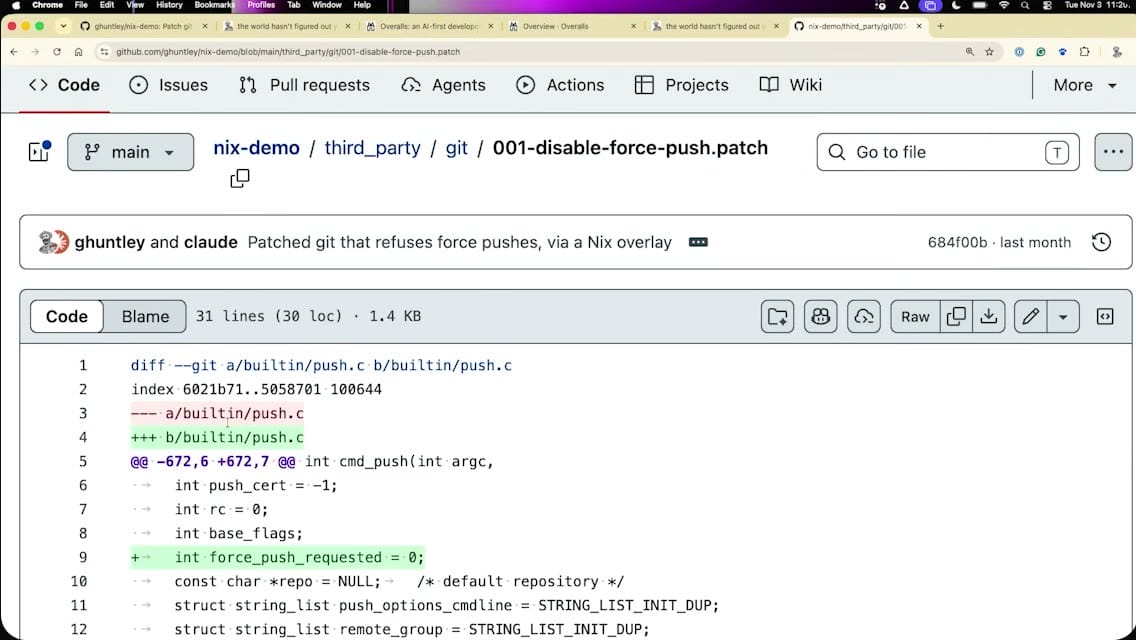
How did I get the custom patches? I asked Claude: Can you please use Nix and create a custom overlay that removes force push? Done. Now a set of Unix patches is applied to git automatically whenever I'm in that environment. And it's not just that environment. It could be Docker, or a production host, wherever you like.
This one little pattern makes the entire world patchable. You're no longer waiting on someone upstream to merge a bug fix. You just route around it.
patch the planet
There's no hidden magic and no skeletons in the closet. I import the overlay and Nix handles the rest. You might think mise is good software. It's not; it's a package manager like Homebrew. Does it have this level of functionality? Nix lets you patch anything, including the operating system kernel, and then deploy that custom version across your fleet.
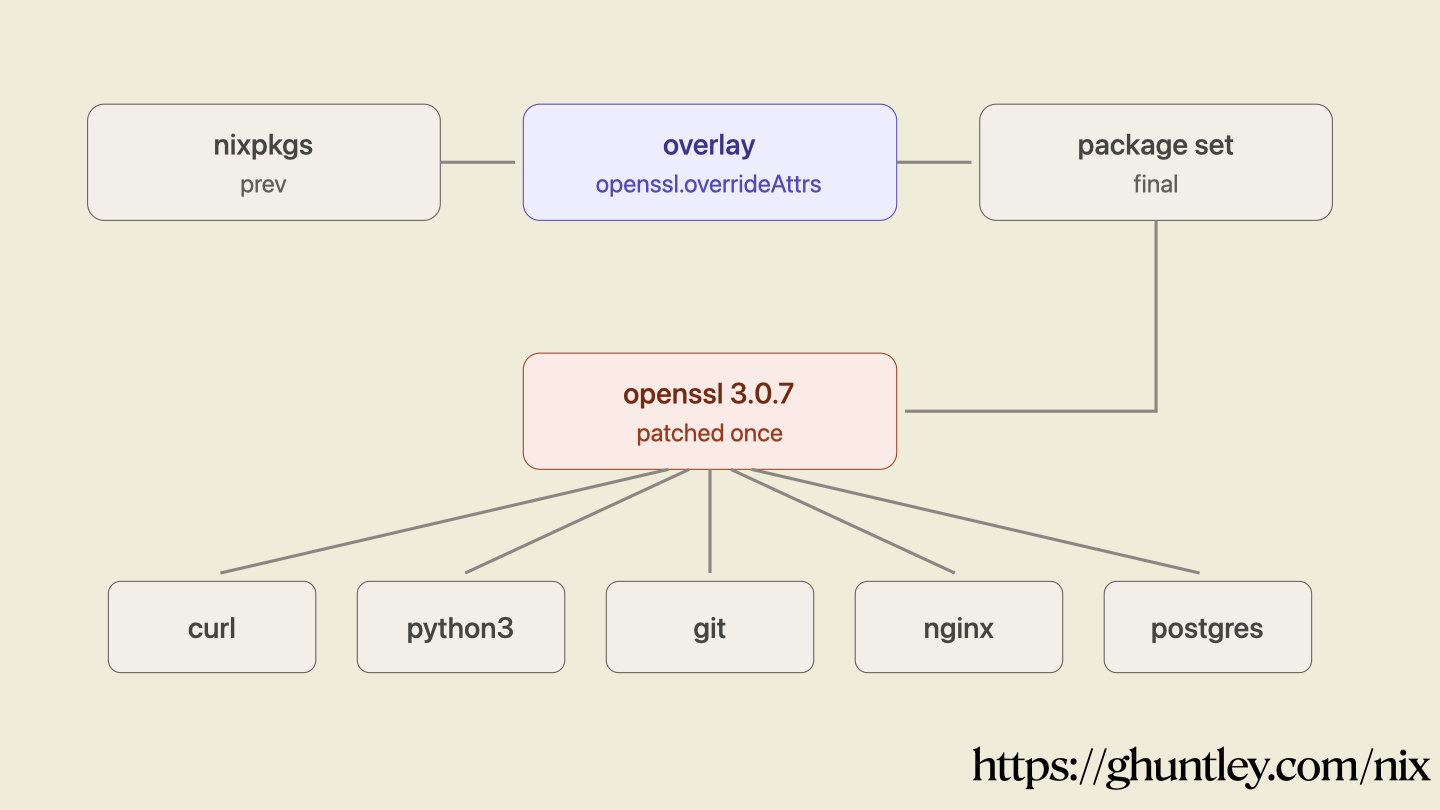
About a month before the incidents, I wrote about what happens when there's a critical fault in OpenSSL. You can update OpenSSL. Cool. But what about when it's a transitive dependency? OpenSSL is used by Nginx and Postgres, so it isn't just a matter of patching OpenSSL itself. That's why we never patched things manually. With a single source of truth for OpenSSL, you apply a monkey patch just like I did with git, and Nix recompiles the world. Every transitive dependency gets the custom version.
Nix has good caching and remote builders, similar to Bazel, so this doesn't mean compiling forever. CI compiles the software once, validates it, and publishes it to the cache, and your developer environments and sandboxes download from it. Simple.
So the question I want to put to you is: how much productivity did you lose two weeks ago during those security incidents?
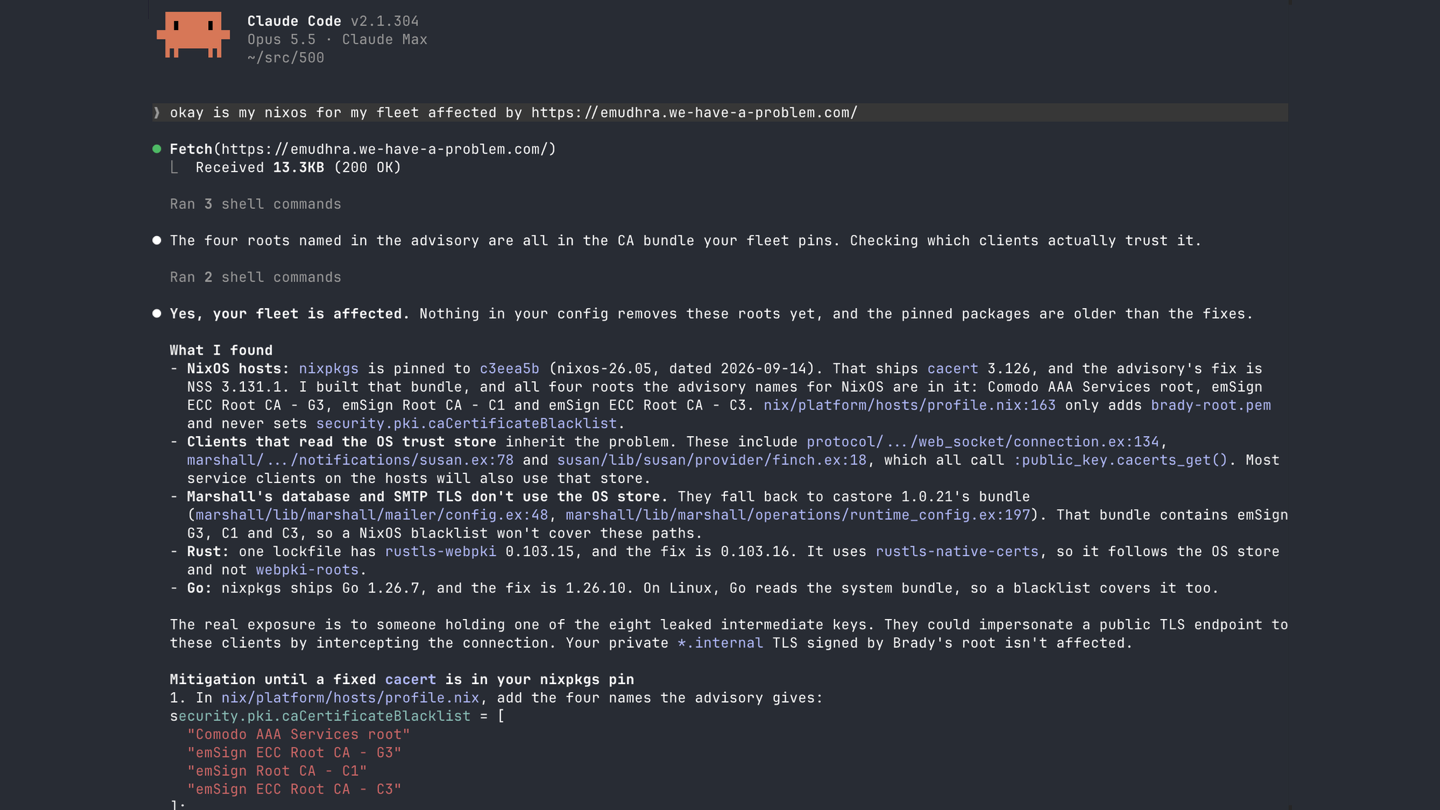
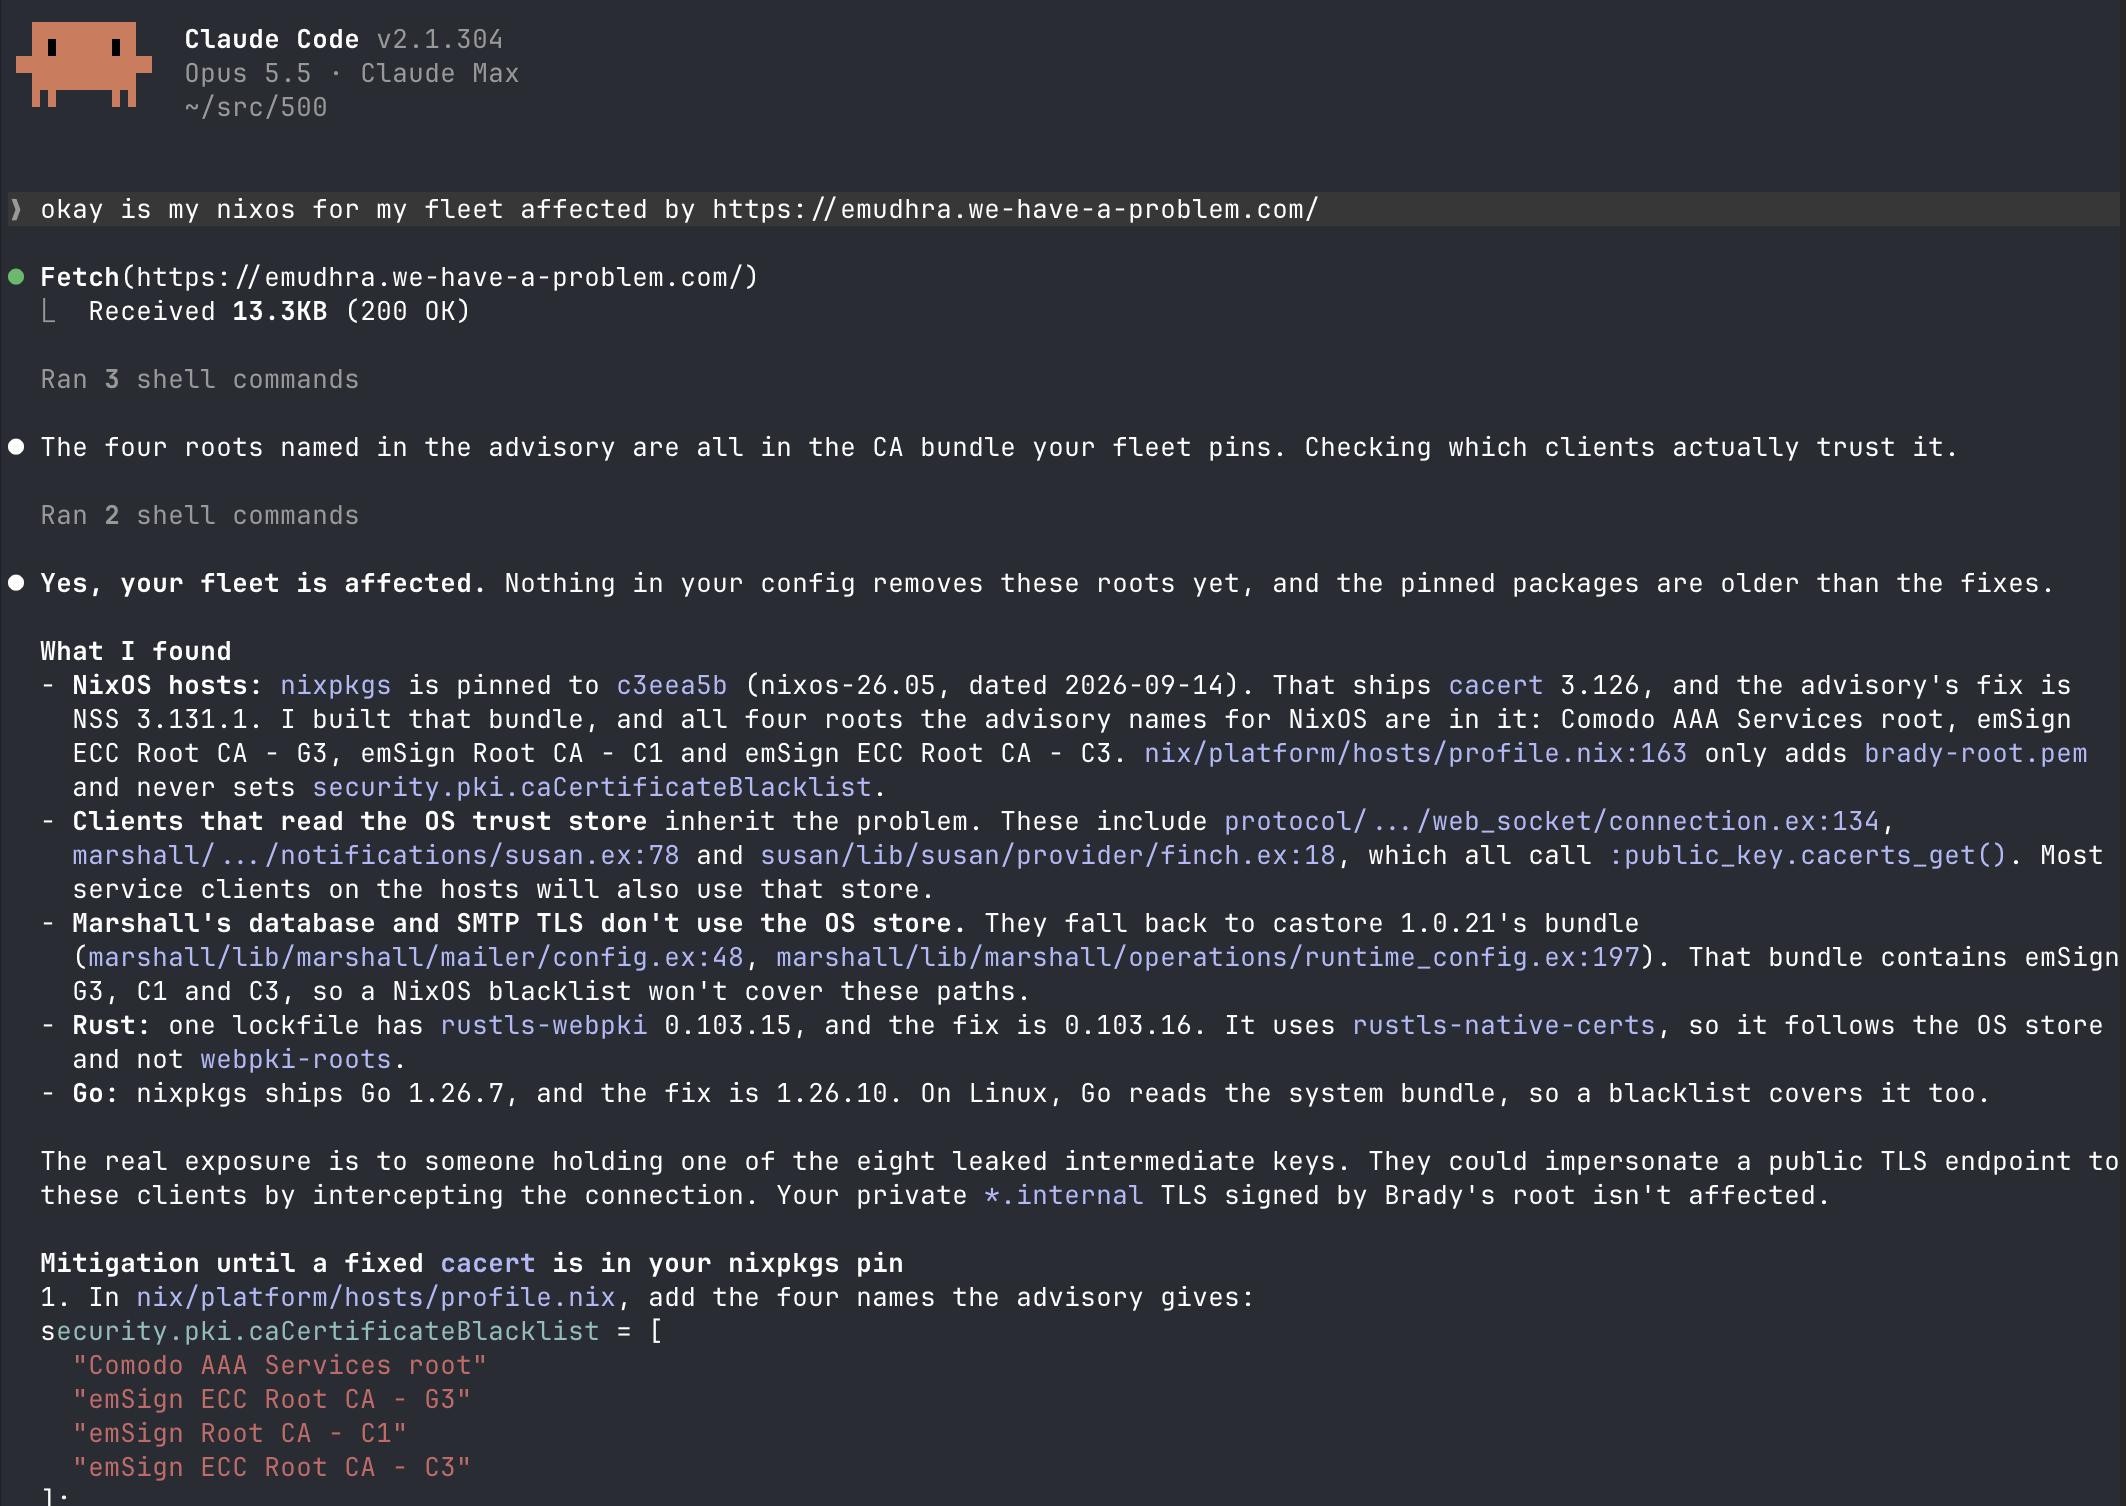
I didn't lose any sleep, folks, because I have a single source of truth. I opened Claude and asked whether my fleet was affected.
It said yes, and from there it applied the monkey patches it needed and updated the refs, dependencies, and pins. Because everything flows from that source of truth, the transitive dependencies recompiled automatically. Done. I'm living the nirvana life over here, and you could be too. You just have to know this exists.
the AGENTS.md reminder trick
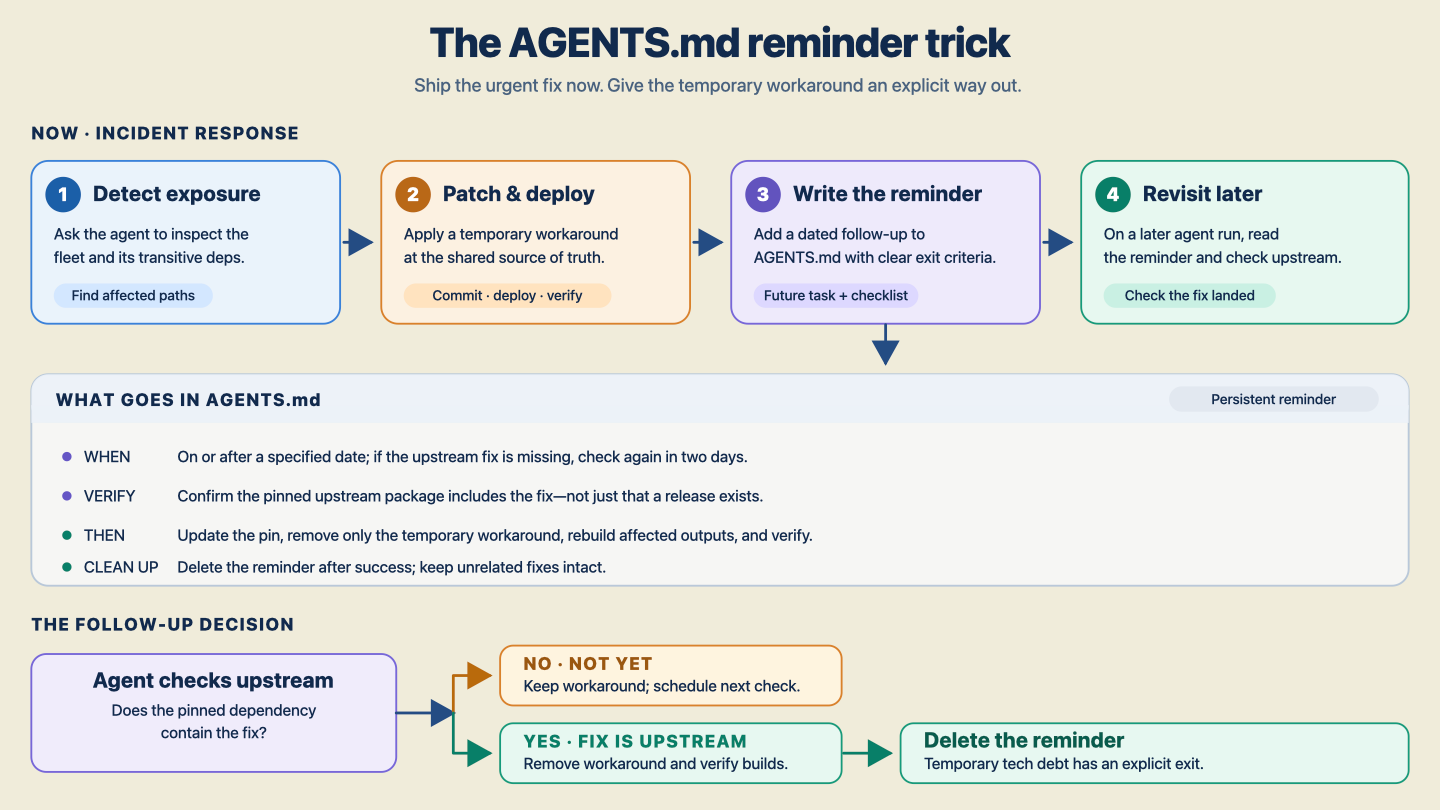
There was one cute trick I did. After the "am I affected?" prompt, I had some temporary monkey patches in place, similar to the git overlay. So I issued another prompt: update the AGENTS.md, and in seven days' time, get rid of my patches.
Instead of creating a Jira ticket, I added a reminder to my AGENTS.md. The next developer or agent to pick up that machine automatically did the housekeeping, and backed out the monkey patches and pins because upstream had been fixed. This is the easiest security maintenance I've ever done. Every time there's a security issue, I use these two tricks.
If you optimise for this, your security incident response gets faster, and your productivity for factories and everything else gets faster too. The answer for AI is engineering.
root, but only in a sandbox
I had ten minutes left, so I did a bonus round on loops. Everyone has their own way of doing loop engineering. There are no best practices, and my way is very different from Steve's. Surprise: mine involves Nix, which has a very powerful testing primitive.
When I run my loops, I give my agents sudo. They run as root. Would you do that on an Ubuntu machine? Hell no. But a throwaway Nix developer machine has some unique properties. I can run these loops with sudo, which lets the agent inspect everything from the database to the journals, and it's safe because I designed the operating environment for it.
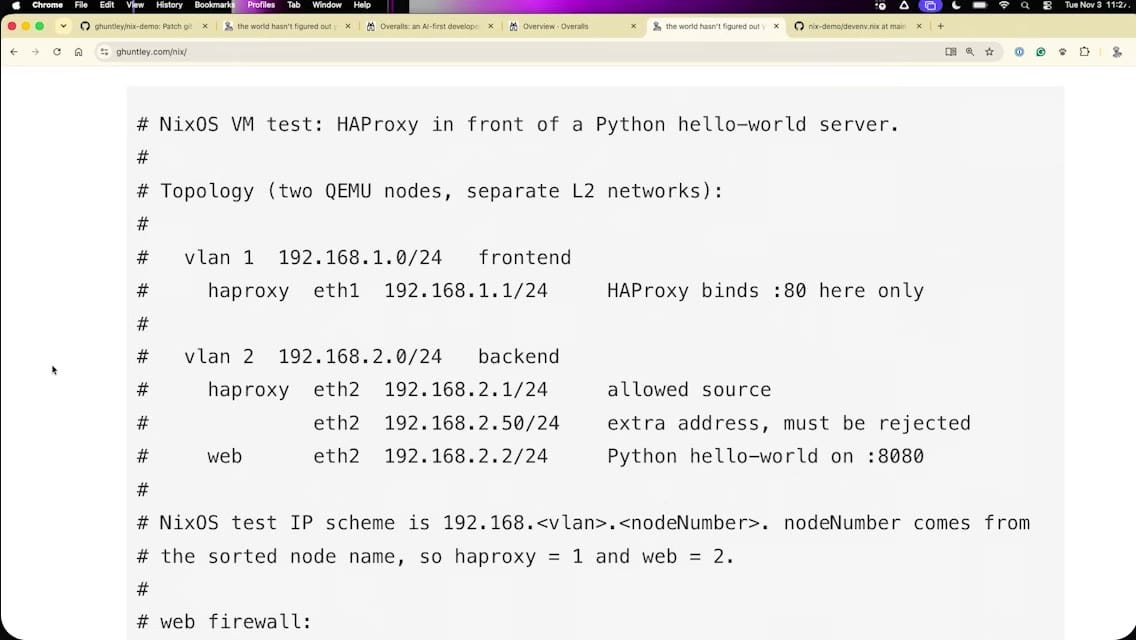
Here's why that matters. Nix has a testing framework called the NixOS test. Imagine two web servers with a load balancer in front, on different network VLANs. How would you normally test that? It would be really hard. With Nix, you define what you need; it creates all the machines, and you can assert that your network rules hold.
When I run my loops, the entire operating system, the fleet and the higher-tier stack are all under test, integrated from day one. When the agent finishes a unit of work, I test it on exactly what would be production infrastructure, because the infrastructure is defined as code. I can deploy that increment somewhere as a preview environment. Run production from Nix flakes, spin up something identical to production, test the hell out of it, and if it's green, it will be correct when you apply that flake to production.
Having said all that: do not run agents with Nix as root on production hosts, and do not connect agents to production databases. Ever. If you need to reproduce something, build a workflow that duplicates the database and restrict the heck out of outbound network access. Dev parity really is equal at this point. One source of truth, one way up.
don't let the loop close
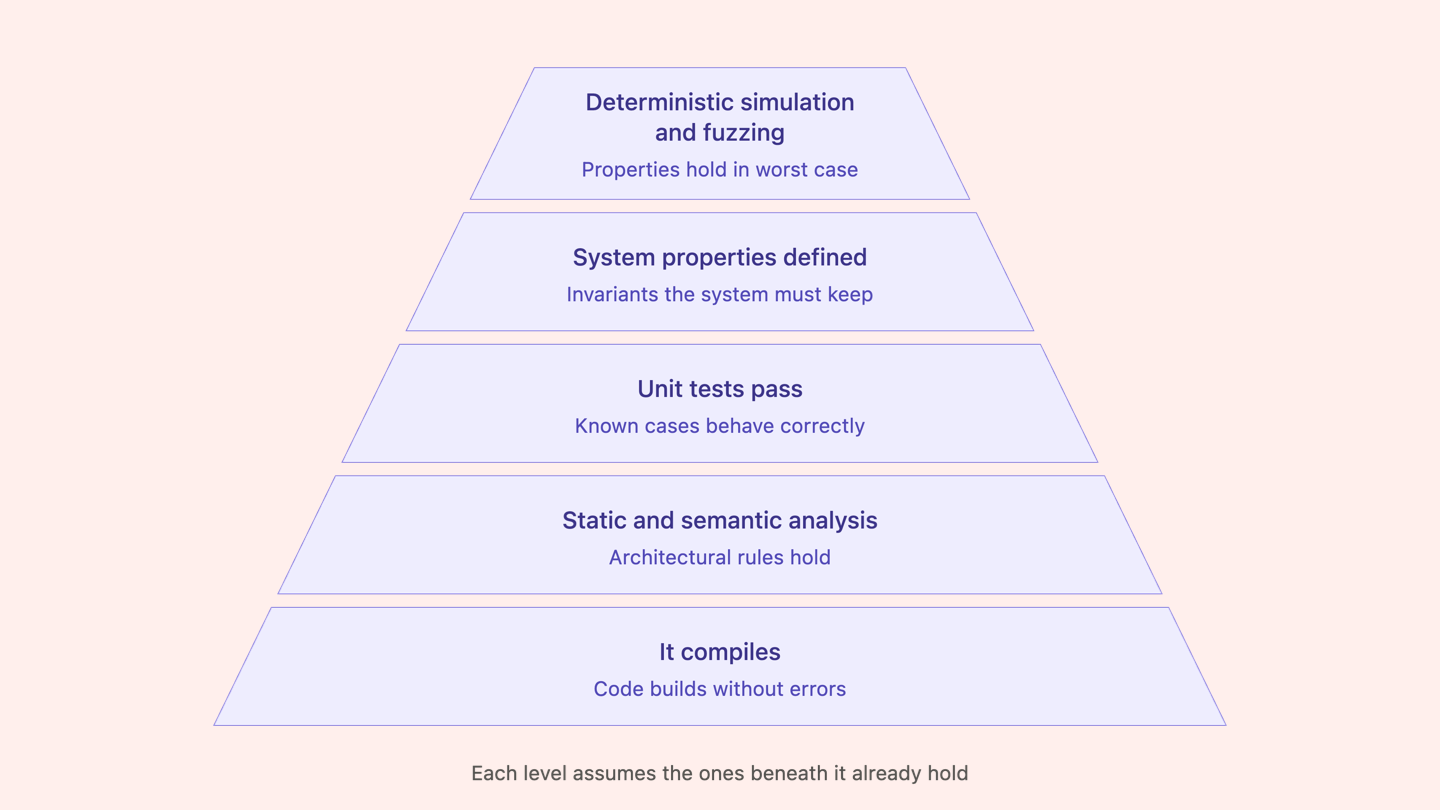
Ralph was never just about loops. It was about stopping the loop from closing on bad code. The loop generates code, commits it, compiles it, and so on. The best way to stop it closing on bad output is deterministic checks. These aren't skills. This is engineering again.
You can block a git push if the software doesn't compile. That's a pre-commit hook, or prek, and you can engineer a lot of back pressure with hooks. Then add static analysis, such as "this domain must never be coupled to that domain". Say you have an API domain and a SQL domain. You don't want SQL to reference the API. That would normally be an architecture review, but agents are pretty dumb and will do it anyway. Wondering how to solve your code review problems? Engineer away much of the need for code review with checks like these, using static and semantic analysis from your language's language service. There's so much you can do. You just have to ask.
property-based testing
Next, unit tests. The problem with unit tests is that they only test what you specify, so edge cases slip through. That's where property-based testing comes in. It has been around for years, and you should be using it.
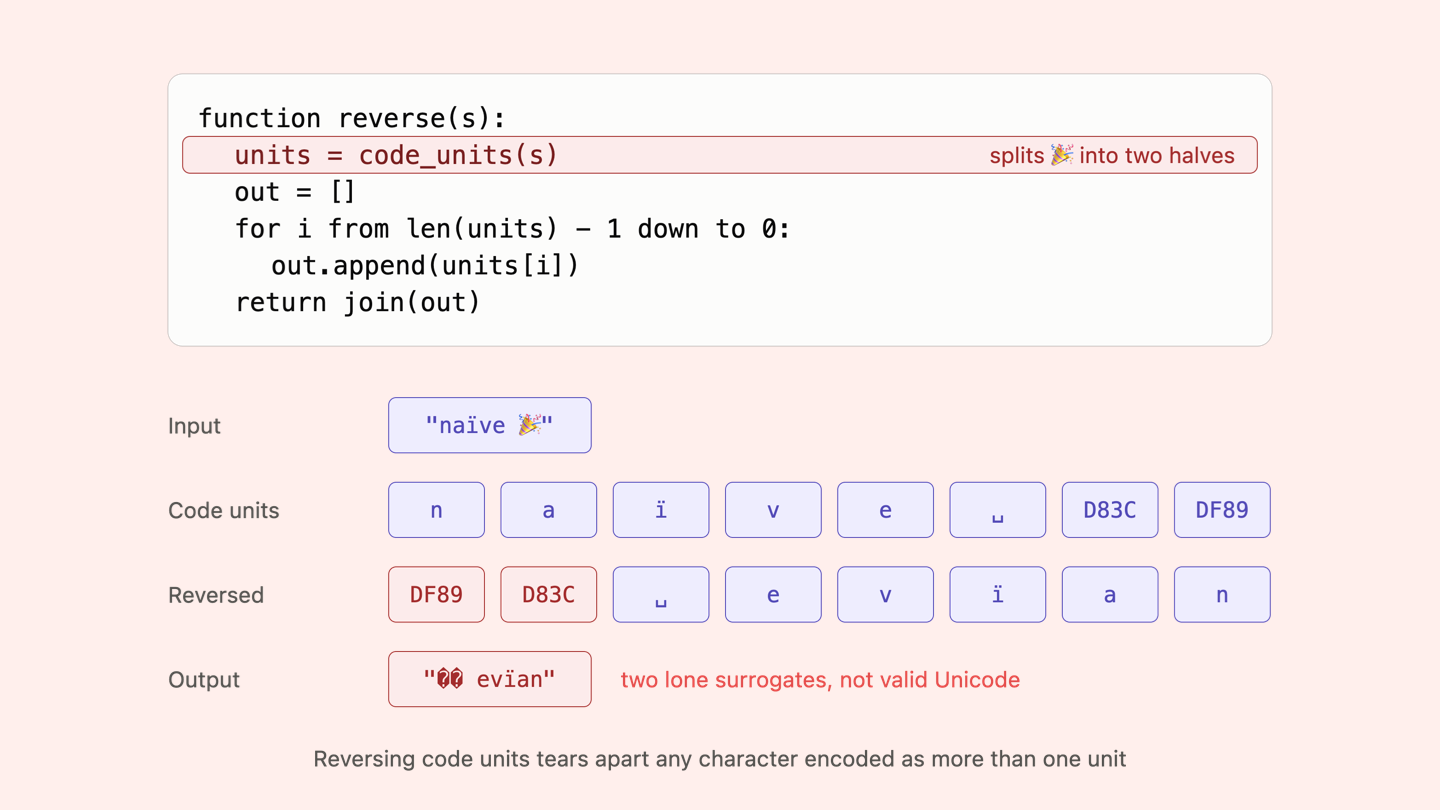
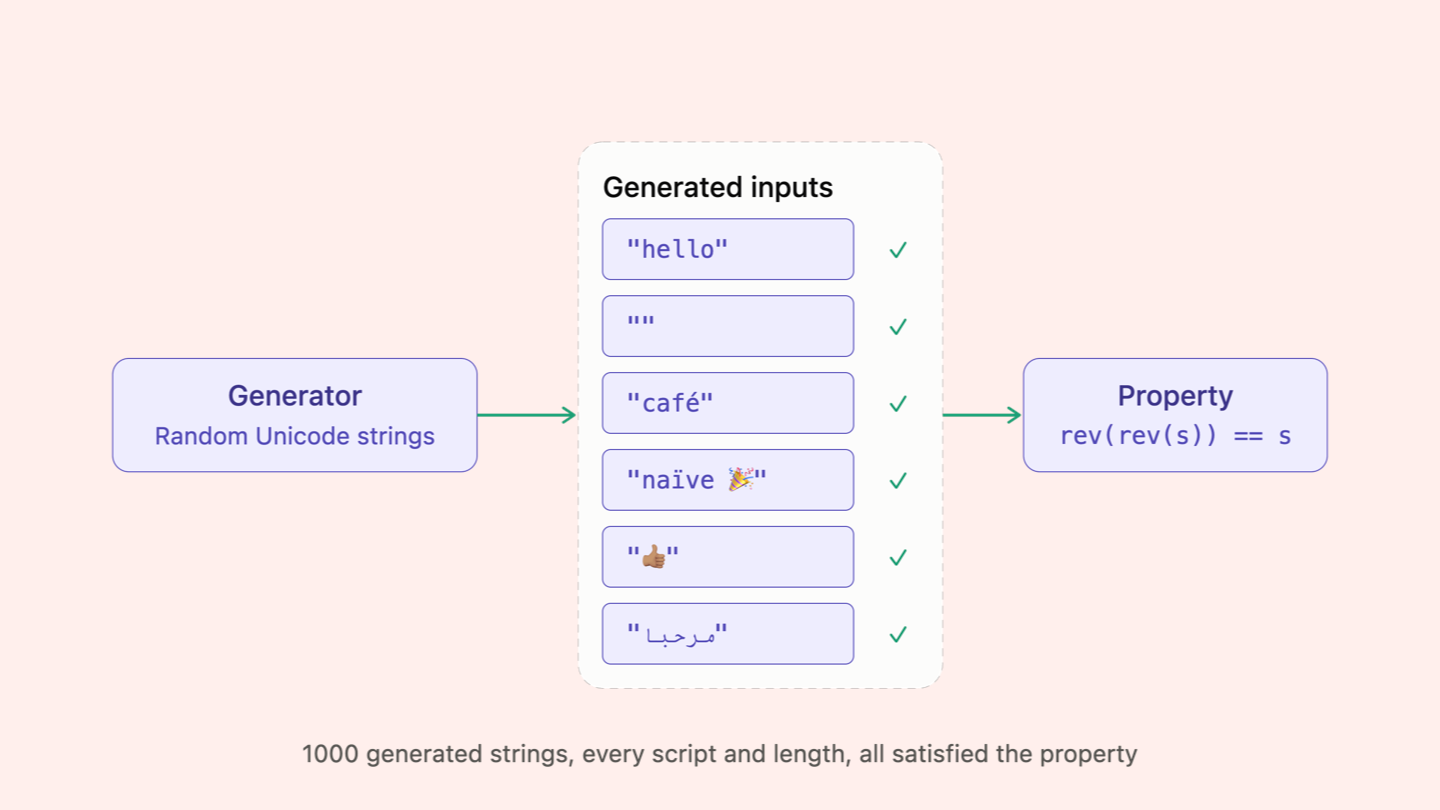
Say you have a function that reverses a string, and the implementation is faulty because it doesn't support Unicode or emoji. I never wrote that test, so it slips through. That's a whole category of problems.
With property-based testing, a generator feeds in random strings, emoji, huge strings and long strings, and keeps exploring the state space to check that your property holds. The property here is that reversing a string twice gives you back the original string. And I'm not just talking about reversing strings. I'm talking about properties like "a customer who asks for a refund is only refunded once", across the whole lifecycle and all of your microservices. Properties take some getting used to, but they're really cool.
bombadil and hegel
At Antithesis, validation and verification of software is what we do. We have a library called Bombadil. You should ditch Playwright, folks, and I'm not just talking my book. Bombadil lets you write a property, such as "the user always has the ability to log out". It loads your plain JavaScript or TypeScript application in a web browser and puts it through hell: rotating the screen, changing dimensions, going full screen, and committing every random act of violence it can against your app until the property either holds or fails. When it fails, you get a counterexample: a reproduction of exactly how it failed.
Fun fact: back in February we woke up to find PewDiePie using it, and we still don't know how, because this is academic knowledge, not popular knowledge. Maybe it's in the model weights.
We also have Hegel: a small core library written in Rust, with sugar on top for each programming language. You might know its predecessor, Hypothesis. Same team, same tech, but now we're bringing it to every programming language. Do these two things in your codebase and, beyond solving your patching woes, you'll get a massive uplift across your organisation. They're free. You just have to know they exist and use them.
The holy grail of build systems and package managers is bit-reproducible1 builds. This is such a desired trait that nearly every Linux distribution has a reproducible builds project to track the progress and validity of their builds.
Why is bit-reproducibility so important? Trust. You can trust that the software you are running has not been tampered with and is the same as what the developers intended if you can verify that when built from source, the output is identical.
Making software bit-reproducible though is hard. There are a lot of ways that can introduce non-determinism into a build: timestamps, random seeds, thread scheduling, and more. Most distributions that have achieved “reproducible builds” have done so for only a subset of their packages, usually those that comprise the core of the ISO or distribution.
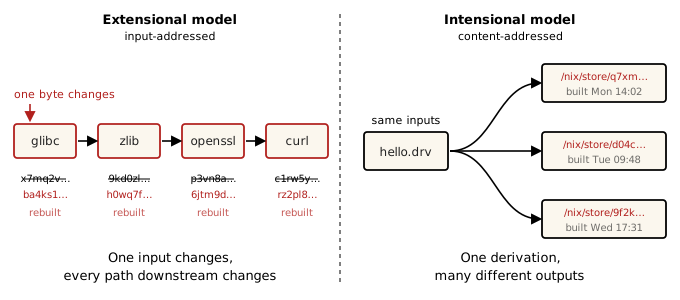
Nix’s default model, the extensional model (input-addressed), famously works around the need for bit-reproducibility by hashing the inputs to a build and using that hash as the store path. This lets the build be repeatable even if the output is not bit-for-bit identical. It is an incredibly pragmatic solution to making builds repeatable, but it does not solve the problem of trust. We are still trusting the outputs uploaded to cache.nixos.org have not been tampered with.
Nix also has an experimental content-addressed model (intensional model) where the /nix/store paths are based on the content of the output, but crucially, it does not guarantee that the builds are bit-reproducible.
This leaves us with an undesirable situation regardless of the model. For the extensional model, the smallest change in the inputs changes the store path which causes a cascade of rebuilds. For the intensional model, a single derivation can produce multiple different outputs.
What if every build could be bit-reproducible? What would that mean for Nix and the extensional model?
I have been working on Rewind, a deterministic virtual machine. It runs builds in a deterministic environment, which so far has mostly been used to investigate bugs. I have been thinking about what else a platform that runs builds deterministically makes possible.
When we try to make a build bit-reproducible, we usually go hunting for the sources of non-determinism: timestamps, random seeds, thread order. These are inputs the derivation does not account for, so they are not hashed into the store path.
A simpler approach is to run the whole build inside a deterministic machine.
Eelco’s thesis says outright that the extensional model assumes the builder is impure (§5.7).
Build operations in general are not pure: the contents that a builder stores in the output path can depend on impure factors such as the system time. […] Thus, while any derivation can have a potentially infinite set of output path contents that can be produced by an execution of its builder, we view the elements of that set as interchangeable.
But this is a model—an assumption about builders.
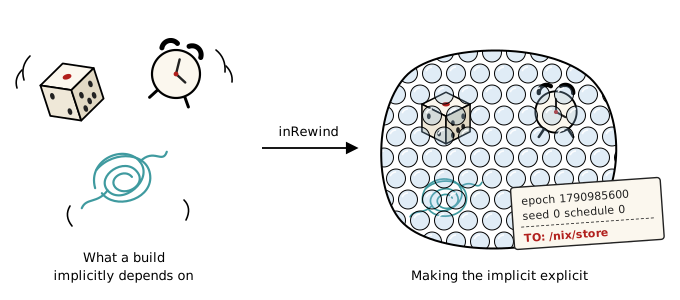
Running a build within Rewind captures all of the implicit inputs to a build and makes them explicit, which makes any build bit-reproducible. 🤯
We can wrap any derivation in Rewind with a Nix function. inRewind takes the machine’s inputs and a derivation, and returns the same derivation with its builder running inside Rewind:2
It works on any derivation and the resulting derivation is bit-reproducible every time.3
Let’s look at a simple example of a build that is not bit-reproducible, and how when wrapped in Rewind, it becomes bit-reproducible.
Here is a simple C program that prints a greeting and depends on a library. The derivation adds a build id and a build time to the output similar to what release builds often do to “stamp” their builds. The build id and build time are two common sources of non-determinism in builds.
We have wrapped the derivation in a function to control whether the build runs in Rewind or not, and whether the build is content-addressed or not.
Built on the host under the input-addressed model, greet fails --check:
$nix-build -A greet --arg ca false--checkerror: derivation '/nix/store/2hm8ram0…-greet.drv' may not be deterministic:
output "/nix/store/kjx5rzjk…-greet" differs
Built in Rewind, the same derivation passes:
$nix-build -A greet --arg ca false--argstr machine rewind
building '/nix/store/bxh3c25a…-greet.drv'...
inRewind: run c7be39a9ea6be3de exited:0 after 2157 steps
/nix/store/lrx579rx…-greet
$nix-build -A greet --arg ca false--argstr machine rewind --checkchecking outputs of '/nix/store/bxh3c25a…-greet.drv'...
inRewind: run c7be39a9ea6be3de exited:0 after 2157 steps
/nix/store/lrx579rx…-greet
$nix-build -A hello --arg ca false--argstr machine rewind
building '/nix/store/1bkqfsg3…-hello.drv'...
inRewind: run 54b543a1c6b65b46 exited:0 after 2439 steps
/nix/store/y8r98q35…-hello
$./result/bin/hello
hello, world
build aabe0f2b-f5d1-477f-b3b8-3e7f1755dc0f at 2026-10-03T00:00:00Z
The UUID still comes from the kernel’s random pool and the time still comes from the clock. They are the same on every build because the pool’s seed and the clock’s start are initialized from the same values.
Nice! We just got a build that is bit-reproducible even if it’s not content-addressed.
You can find more details of the library and even making Rewind a Nix external-builder on Rewind’s Nix build reference.
What does that mean for the content-addressed model?
Since the outputs are not bit-reproducible, the same derivation gets a different /nix/store path on each rebuild.4
$nix-build -A hello --arg ca true--store ./store-a
resolved derivation: '/nix/store/5v566cv6…-hello.drv' ->'/nix/store/83qn27rk…-hello.drv'...
/nix/store/rwaisri0…-hello
$nix-build -A hello --arg ca true--store ./store-b
resolved derivation: '/nix/store/5v566cv6…-hello.drv' ->'/nix/store/0rjbw8s8…-hello.drv'...
/nix/store/wvy9zby9…-hello
$nix realisation info -f. greet --arg ca true--store ./store-a
rbzv0mbw…-greet.drv^out ->bryxd8dy…-greet
$nix realisation info -f. greet --arg ca true--store ./store-b
rbzv0mbw…-greet.drv^out ->hh2v12cs…-greet
Producing multiple variants is problematic and the thesis notes the consequence (§6.4.1): you can end up with a closure that contains more than one variant of the same derivation.
The fact that a derivation can resolve to any number of output paths due to impurity, leads to the problem that we might end up with a closure that contains more than one element from the output equivalence class of a derivation.
With inRewind, both stores build the same bytes and print the same path:5
$nix-build -A hello --arg ca true--argstr machine rewind --store ./store-a
inRewind: run 4d9de4235038d6d0 exited:0 after 2158 steps
inRewind: run 3a2797f47898d7ce exited:0 after 2438 steps
/nix/store/daqfk0jm…-hello
$nix-build -A hello --arg ca true--argstr machine rewind --store ./store-b
inRewind: run 4d9de4235038d6d0 exited:0 after 2158 steps
inRewind: run 3a2797f47898d7ce exited:0 after 2438 steps
/nix/store/daqfk0jm…-hello
$nix realisation info -f. greet --arg ca true--argstr machine rewind --store ./store-a
q6i384y2…-greet.drv^out ->kvjqc292…-greet
$nix realisation info -f. greet --arg ca true--argstr machine rewind --store ./store-b
q6i384y2…-greet.drv^out ->kvjqc292…-greet
One derivation, one path, in every store.
Bit-reproducible outputs also mean cache hits across machines. If the bytes are the same, the content address is the same, and a path one machine built is a hit for every other: early cutoff optimization ftw!
Both panels collapse
When we make every build bit-reproducible, the two models collapse into one. What does this mean for the extensional model?
The extensional model was a wonderful pragmatic solution to a world where determinism was not guaranteed but it came at a cost: a single change in the inputs cascades through every downstream derivation. Adoption to content-addressed derivations has been slow similarly because producing multiple outputs makes it hard to reason about the closure of a derivation. When we have guaranteed bit-reproducibility, both problems disappear.
Having a stable platform with which to build software reproducibly might completely change the toil of working to make software reproducible and change the economics of whether to leverage content-addressed derivations.
The usefulness of a reproducible environment is not well explored and I think there are other interesting use cases for it. One that I’m exploring is to use it to make the act of performing a benchmark reproducible.
Aside
The cost is that the machine is now an input, Rewind included. Upgrade Rewind and every wrapped derivation rebuilds. Build on an Intel machine and you get a different, equally reproducible, output than on AMD.
A tool that was designed for bug investigation and reproducibility of builds might have a larger impact on the software ecosystem than I had originally thought. It is a tool that can be used to make software more trustworthy, and all the wonderful beefits that come with it.
It’s lame that I have to keep clarifying it as “bit” reproducible but the term is overloaded. ↩
Rewind is a KVM-based virtual machine, so it requires a host with KVM support. It also requires the rewind-amd or rewind-intel system feature to be advertised by the host. ↩
On the same Rewind version and the same CPU vendor. Fixed-output derivations are refused, because they need the network and the VM has none. ↩
Two stores are used to illustrate buids on different machines. ↩
Nix 2.35 changed how it hashes an output that mentions its own path, so the content address of such an output depends on the Nix version. ↩
Profile-guided optimization (PGO) is an easy way to speed up a program, especially if the workload is somewhat stable. In leaving performance on the table, I built a profile-guided sqlite3 variant for a 1.32x speedup for our SELECT workloads.
Compilers and interpreters make excellent candidates for PGO, since the training workload looks like the real one: compiling code is compiling code. They also benefit the most from it, since they underpin so many other programs; a small speedup in the compiler or interpreter can have a large effect on the overall system performance.
Despite their benefits, PGO is not widely used in package-managers. For instance, Python and GCC both support profile-guided builds but are explicitly disabled in Nixpkgs (Python, GCC), and Guix (Python).
Aside
Nix and Guix both do not need reproducible builds to stay consistent. Their store paths are input-addressed, meaning the path is derived from the inputs only. They can produce outputs with different bytes claiming the same path, and whichever one reaches the binary cache first is the one everybody downloads.
Why are they disabled? Reproducibility!
Many package managers have reproducible builds as a goal, and PGO is not reproducible.
When compiling from the same source on independent infrastructure yields bit-by-bit identical results, this gives confidence that the build infrastructure was not compromised and the artifact really does correspond to the source.
To build a profile-guided program, the compiler first builds it with instrumentation. Running that build on a training workload collects profile data, which is the “profile-guided” part. The compiler then uses the profile to optimize the program in a second build.1 The problem is that the training run is not reproducible,2 so the profile can differ between builds, and with it the optimized binary.
We want profile-guided builds though, because it is such an easy way to speed up a program. Can we make PGO reproducible so that we can have our cake and eat it too?
I have been building Rewind, a deterministic virtual machine. A program’s execution becomes a pure function of its inputs. I have primarily been using it to investigate and find bugs3 or as a way to make builds bit-reproducible. It occurred to me that the same properties that make Rewind useful for debugging and reproducible builds can also make PGO reproducible.
Here is a program whose profile depends on the order in which its threads run. It hands 100,000 jobs to two workers: one worker always runs checksum and the other always runs compress, so how often each function runs depends on which worker takes each job. That depends on the thread schedule, which is non-deterministic, so the profile is non-deterministic too.
staticvoid*worker(void*arg){longid=(long)arg,acc=0;for(intjob;(job=take())!=DONE;){/* The seed picks which worker checksums and which compresses. */if((id^seed)&1){acc+=checksum(job^seed);}else{acc+=compress((job^seed)&0xffff);}}return(void*)acc;}
shuffle.c
/* main() hands jobs to two workers through a small queue. Which worker
* takes a job decides which code path runs, so the profile depends on
* the schedule. */#include<pthread.h>
#include<stdio.h>
#include<sys/random.h>#define JOBS 100000
#define SLOTS 8
#define DONE -1
staticpthread_mutex_tlock=PTHREAD_MUTEX_INITIALIZER;staticpthread_cond_tnot_empty=PTHREAD_COND_INITIALIZER;staticpthread_cond_tnot_full=PTHREAD_COND_INITIALIZER;staticintqueue[SLOTS],head,count;staticunsignedseed;__attribute__((noinline))staticlongchecksum(longx){for(inti=0;i<64;i++){x=x*6364136223846793005L+1442695040888963407L;}returnx;}__attribute__((noinline))staticlongcompress(longx){while(x>1){x=(x&1)?3*x+1:x/2;}returnx;}staticvoidput(intjob){pthread_mutex_lock(&lock);while(count==SLOTS){pthread_cond_wait(¬_full,&lock);}queue[(head+count++)%SLOTS]=job;pthread_cond_signal(¬_empty);pthread_mutex_unlock(&lock);}staticinttake(void){pthread_mutex_lock(&lock);while(count==0){pthread_cond_wait(¬_empty,&lock);}intjob=queue[head];head=(head+1)%SLOTS;count--;pthread_cond_signal(¬_full);pthread_mutex_unlock(&lock);returnjob;}staticvoid*worker(void*arg){longid=(long)arg,acc=0;for(intjob;(job=take())!=DONE;){/* The seed picks which worker checksums and which compresses. */if((id^seed)&1){acc+=checksum(job^seed);}else{acc+=compress((job^seed)&0xffff);}}return(void*)acc;}intmain(void){pthread_tt[2];getrandom(&seed,sizeofseed,0);for(longi=0;i<2;i++){pthread_create(&t[i],NULL,worker,(void*)i);}for(intjob=0;job<JOBS;job++){put(job);}for(inti=0;i<2;i++){put(DONE);}for(inti=0;i<2;i++){pthread_join(t[i],NULL);}puts("done");return0;}
A typical Nix derivation does all three PGO steps in its buildPhase, and keeps the profile in $out so we can inspect it:
{pkgs?import<nixpkgs>{},}:pkgs.stdenv.mkDerivation{name="shuffle-pgo";src=./shuffle.c;dontUnpack=true;buildPhase='' cp $src shuffle.c # 1. Build with instrumentation. cc -O2 -pthread -fprofile-generate -c shuffle.c -o shuffle.o cc -pthread -fprofile-generate shuffle.o -o shuffle # 2. Train: the run writes its counters to shuffle.gcda. ./shuffle # 3. Rebuild using the counters. cc -O2 -pthread -fprofile-use -c shuffle.c -o shuffle.o cc -pthread shuffle.o -o shuffle '';installPhase='' install -Dm755 shuffle $out/bin/shuffle install -Dm644 shuffle.gcda $out/share/shuffle.gcda '';}
Build it, then ask Nix to build it again and compare:
$nix-build
/nix/store/3ynxjxlc05afxwk675ysdbvi7vp4vpqm-shuffle-pgo
$nix-build --check-Kerror: derivation '/nix/store/f4522l48yf8wdd488yg4p604xqx1i2z3-shuffle-pgo.drv' may not be deterministic: output "/nix/store/3ynxjxlc05afxwk675ysdbvi7vp4vpqm-shuffle-pgo" differs from "/nix/store/3ynxjxlc05afxwk675ysdbvi7vp4vpqm-shuffle-pgo.check"
Rebuilding the derivation multiple times and reading the profile shows that the counts are different every time.
build
checksum calls
compress calls
ran first
binary
original
55,163
44,837
compress
ba528bca18f5
check 1
57,725
42,275
checksum
2bb3ff5e19d2
check 2
57,066
42,934
compress
ba528bca18f5
check 3
57,443
42,557
compress
ba528bca18f5
check 4
58,522
41,478
checksum
2bb3ff5e19d2
check 5
58,486
41,514
checksum
2bb3ff5e19d2
check 6
57,799
42,201
checksum
2bb3ff5e19d2
Aside
Interestingly, only two binaries are produced (ba528bca18f5 and 2bb3ff5e19d2), but the profile is different every time. -fprofile-use turns on -fprofile-reorder-functions, which lays functions out in order of first use. We could disable that and get the same binary every time for this toy, but the counts still change, and in a real program they decide inlining and block layout.
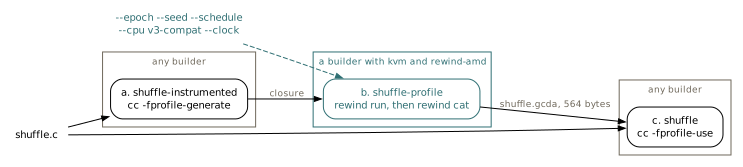
Inside Rewind the run is fixed by its boot clock, seed and thread schedule, so the same inputs give the same profile. To use Rewind, we split the derivation into three separate derivations: one for the instrumented build, one for the training run, and one for the final build. Compiling is already deterministic, so the two compiles remai ordinary derivations. Only the training run in the middle needs a deterministic machine, and that one runs inside Rewind.n
The one part of the deterministic VM the model does not fix is the vendor. Intel and AMD differ in ways that cannot be hidden from the guest, so they are exposed to the program and could change the program execution and therefore the profile. That means the training run must be pinned to a vendor, and the derivation must require that vendor.4
{pkgs?import<nixpkgs>{},rewind?(builtins.getFlake"github:fzakaria/rewindvm/v0.12.0").packages.${pkgs.stdenv.hostPlatform.system}.default,# The CPU vendor to train on. Rewind's fixed CPU model keeps the host's# vendor, so each vendor trains its own profile.vendor?"amd",}:let# What /proc/cpuinfo calls each vendor.vendorIds={amd="AuthenticAMD";intel="GenuineIntel";};# The training run's inputs: the VM's clock at boot, the seed for its# randomness, the thread schedule, and what moves its clock.epoch="1790985600";seed="0";schedule="1";clock="branches";# a. The program built with instrumentation, natively.instrumented=pkgs.runCommandCC"shuffle-instrumented"{}'' cp ${./shuffle.c} shuffle.c cc -O2 -pthread -fprofile-generate -c shuffle.c -o shuffle.o mkdir -p $out/bin cc -pthread -fprofile-generate shuffle.o -o $out/bin/shuffle '';# b. The training run, inside Rewind. The instrumented program writes# its counters to /build/shuffle.gcda, where it was compiled.profile=pkgs.runCommand"shuffle-profile"{nativeBuildInputs=[rewindpkgs.jq];# A builder whose Rewind module says this vendor, with KVM.requiredSystemFeatures=["kvm""rewind-${vendor}"];closure=pkgs.closureInfo{rootPaths=[instrumented];};}'' export HOME=$TMPDIR # Another vendor would train another profile: refuse instead. if ! grep -q "vendor_id.*: ${vendorIds.${vendor}}$" /proc/cpuinfo; then echo "this profile trains on ${vendor}; this builder is $(grep -m1 vendor_id /proc/cpuinfo)" >&2 exit 1 fi # A root filesystem holding the program and its closure. mkdir -p root/nix/store root/build xargs -I{} cp -a {} root/nix/store/ < $closure/store-paths rewind run --root root --cwd /build --json \ --epoch ${epoch} --seed ${seed} --schedule ${schedule} \ --cpu v3-compat --clock ${clock} \ -- ${instrumented}/bin/shuffle > run.json jq . run.json >&2 # Read the profile as it was when the run ended. id=$(jq -r .id run.json) steps=$(jq -r .steps run.json) mkdir -p $out rewind cat --progress off $id $steps /build/shuffle.gcda > $out/shuffle.gcda '';in# c. The program rebuilt with the profile, natively.pkgs.runCommandCC"shuffle"{passthru={inheritinstrumentedprofile;};}'' cp ${./shuffle.c} shuffle.c cp ${profile}/shuffle.gcda shuffle.gcda cc -O2 -pthread -fprofile-use -c shuffle.c -o shuffle.o mkdir -p $out/bin cc -pthread shuffle.o -o $out/bin/shuffle''
Nix puts /dev/kvm inside the sandbox on a machine that lists kvm in its system-features, as NixOS does by default. kvm alone does not say the machine can train this profile, so the derivation also requires rewind-amd. A builder can opt-in easily through Rewind’s NixOS module:
programs.rewind={enable=true;systemFeature="amd";# AMD only: make the branch counter exact at every boot.amdBranchCounterWorkaround=true;};
Build it, then check both the profile and the final program:
$nix-build
/nix/store/f1yqkk8a3binrq4iqrm6mdl1p7zp5dvv-shuffle
$nix-build -A passthru.profile --check/nix/store/ywv05plinnpg868b0p66b1lpfjnr9sp1-shuffle-profile
$nix-build --check/nix/store/f1yqkk8a3binrq4iqrm6mdl1p7zp5dvv-shuffle
This means our profile-guided build is bit-for-bit reproducible!
The profile is a function of the derivation now along with the other arguments to Rewind: --epoch--seed--schedule--cpu and --clock. If any of those change, the profile changes too.
In our example above, we picked --schedule 1 why?
This is a little beyond the reproducible build story, but picking a workload is a bit-of-an-art. You want to pick a workload that resembles production, so that the profile is useful.
Since our toy-example is heavily influenced by the thread schedule, we can try different schedules and see what profile they produce.
schedule
checksum calls
compress calls
0
100,000
0
1
50,004
49,996
2
100,000
0
3
100,000
0
Three of the four gave every job to one worker, so compress would never run in training, and a profile from them would tell GCC or Clang that compress is dead code. Schedule 1 is closer to what we hypothetically expect which is about a 50/50 split.
In a more realistic program, picking any schedule would likely be fine, since the program’s execution is less dependent on the schedule.
Although our profiles are vendor-specific, having a meaningful way forward to having reproducible profile-guided builds can help unlock a lot of easy performance wins.
Fast Python or reproducible Python? Press both buttons.
The instrumented program counts which branches it takes, and the second build compiles the program again with those counts. The compiler uses them to decide what to inline, which blocks to lay out together, and which functions are hot or cold. ↩
The training run depends on the machine it runs on: the CPU, the clock, thread scheduling and anything else that changes between builds. ↩
Despite how different they look on the surface, Nix, Bazel and buck2 are remarkably similar under the hood. Don’t believe me?
I built a prototype in one store, two frontends to prove it. Turns out though that the similarities are even deeper than I realized.
Upon further reflection, I realized that the intensional model is an even more substantial common denominator. What is the intensional model?
TIP
I’ve written before about Nix’s intensional model, better known as content-addressed (CA) derivations. It has been “experimental” in Nix for years. 🧪
In the intensional model, outputs are addressed by their content, and actions refer to their inputs by content as well. The extensional model instead addresses an output by the recipe and inputs that produced it. Nix also calls this “content-addressed derivations” (CA derivations). Bazel and buck2 don’t name their model, but they use content-addressing as well.
Consider this coincidence: Eelco’s PhD thesis was published in 2006, the same year that Google started development on Blaze, the predecessor of Bazel [cite].
Let’s take a closer look at the three systems with a simple C example and see how all three implement the intensional model. 🥸
// greet.hvoidgreet(constchar*name);// greet.c#include<stdio.h>
#include"greet.h"/* say hi */voidgreet(constchar*name){printf("hello, %s\n",name);}// main.c#include"greet.h"intmain(void){greet("world");return0;}
In the traditional extensional model (input-addressed), a change anywhere upstream of a build action invalidates the action’s output. This occurs even if the change
is irrelevant to the output, such as a comment change in a source file. In contrast, the intensional model (content-addressed) only invalidates an action’s output if the content of the output itself changes.
In our C example, if we were to change the comment in greet.c from say hi to say hello, the compiled object file greet.o would still be byte-for-byte identical, as the comment does not affect the compiled output. In the ideal world, the linking of hello would not need to be redone, as its inputs have not changed in content.
Nix example
{pkgs?import<nixpkgs>{},ca?false}:letextra=pkgs.lib.optionalAttrsca{__contentAddressed=true;};inrec{# The `cp` is needed otherwise the source file's store path ends up# in the object file, which is a leak of the extensional model.greet=pkgs.runCommandCC"greet"extra'' cp ${./greet.h} greet.h; cp ${./greet.c} greet.c mkdir -p $out cc -c greet.c -o $out/greet.o '';hello=pkgs.runCommandCC"hello"extra'' cp ${./greet.h} greet.h; cp ${./main.c} main.c mkdir -p $out/bin cc main.c ${greet}/greet.o -o $out/bin/hello '';}
By default, Nix uses the extensional (input-addressed) model. If we edit the comment and rebuild:
$nix-build -A hello
building '/nix/store/3hwrlpnji5bh5bajdg52s7zbg7ihs6j6-greet.drv'...
building '/nix/store/2k5is7yim1j8pb3qjz89bw45cqzcy2y5-hello.drv'...
/nix/store/122jc3iz6qkrgm907kdz7rrk3lp4qrma-hello
Everything rebuilt. 😩
The store path in the extensional model is a hash of the recipe, and the recipe for hello includes the recipe for greet. Recursion is fun!
Change one byte anywhere upstream and every path downstream changes with it. 🌀
Warning
The two hello binaries are not even byte-identical: the cc-wrapper puts $out/lib in the RUNPATH, so the binary contains its own store path. The extensional model leaks into the bytes. 🙃
If we enable the build to use content-addressed derivations we observe greet rebuilt, but hello did not. 🎉
$nix-build --extra-experimental-features ca-derivations -A hello --arg ca truebuilding '/nix/store/qpa1q7g5yjvhdbnfap4y3r2glzyflyv4-greet.drv'...
resolved derivation: '/nix/store/1xnbxrrprs50879ivzmjpv7cbk44w258-hello.drv' ->'/nix/store/rs2j6r2gvz2vi7nfvqj1s3yxx4lqpa3m-hello.drv'...
/nix/store/l2nrycgcg97vrz4nb59icwz9i04ys8jg-hello
You can read demystifying Nix’s intensional model for a more detailed explanation of how CA derivations work, but the short version is that Nix rewrites hello.drv to point at greet’s content-addressed output instead of greet.drv. The resolved rs2j6r…-hello.drv is the same one we built before the edit.
Since no “input” changed, Nix avoids the rebuild.
This is the same behavior as Bazel and buck2, which are intensional by default.
Bazel and buck2 do not have an input-addressed mode. They always use the intensional model. An action’s key is a hash of its command line (to force rebuilds) and the content digests of its inputs.
A change only travels as far as the bytes actually change. This optimization is called early cutoff, and it is the whole selling point of the intensional model.
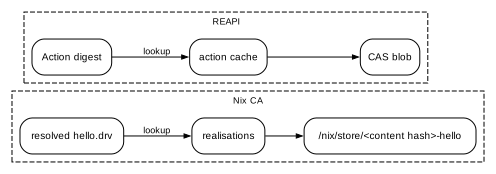
There is a clear mapping between Nix’s CA derivations and Bazel’s action cache.
Nix (intensional)
Bazel / buck2 (REAPI)
resolved derivation
Action: command + input digests
realisation: drv output → store path
action cache: action digest → output digests
content-addressed store path
blob in the CAS
A resolved derivation is a Bazel/buck2 action. 🤯
You may see the output paths in Bazel and buck2 and think they are extensional (i.e. bazel-out/k8-fastbuild/bin/hello), but they are just a convenient place on disk. The real addresses are the digests. buck2 can even make this explicit with declare_output(has_content_based_path=True).
Until dynamic derivations stabilize, people will continue to reach for Bazel and buck2 for the granularity on large builds. The intensional model is a big part of why they are so fast, and Nix has the same model. The two implementations are nearly identical in concept.
Nix described the intensional model in 2006. Google started building on it the same year. Twenty years later, maybe it’s time they compared notes. 🥸
Debuggers are an incredibly powerful and useful tool, but they mostly show you only the present and let you move forward.1 Inspecting the present can help you understand the past, but is that a limitation we must accept?
What if you could travel back in time to see what happened? What if you could see the exact moment a value was written, and who wrote it? What if you could run your debugger backwards?
Rewind is a deterministic virtual machine that records a program’s execution once, and then lets you replay it identically, many times. This lets you run the debugger backwards, and see the history of a value in memory, including who last read and wrote it.
Turns out that you can go backwards by fast-forwarding.
Going backwards changes how you debug: you can see how a value got there, not just what it is now. In who wrote this byte?rewind blame found the program that wrote a byte of a file. That was the easy case. Every write to a file goes through the kernel, and Rewind’s kernel logs each one. Writes to memory don’t go through the kernel, so there is no log to read.
So instead we go backwards, by running forwards again. This is how rewind blame can tell us who last read and wrote a value in memory, and it is the same trick that lets gdb run backwards as well. Let’s see how it works.
In our example, crucially, there is no lock around the read and write of balance. If the other teller runs in between, one of the deposits is lost.
rewind check runs the program under different thread schedules until one fails:
$rewind check --epoch 1790985600 github:fzakaria/rewindvm#bank
schedule 0: exited:0 4547 steps 2ffd6b62eb30 run b1d6981401d5d15f holds
schedule 1: exited:2 3768 steps run 36036ed36994d7d8 violates same-outcome, sdk
...
failing: run 240115d5505149aa, schedule 1 over steps 3245..3246
failing run violates sdk: step 3292: always "balance-adds-up" failed: balance 310, expected 400
check narrows schedule 1’s failure down to steps 3,245 and 3,246 and records that run, 240115d5, which is the one we will dig into. We expected 400 and got 310. Nine deposits are gone. 😬
rewind blame –at
Our program prints the balance at step 3,291. We can run rewind blame at that step and the variable2 to see who last wrote it:
$rewind blame 240115d5 --at 3291 balance
balance = 310 8 bytes at 0x56055a0ef030, thread 139, bank.c:69
last written at step 3282 by thread 141 (bank)
bank.c:41 teller balance = seen + amount; was 300
other threads just after the write, in step 3282:
thread 139 bank.c:65 main __GI___clone3
searched back to step 3210, 1 keyframe window, 1 write, 3.1s
Rewind goes “backwards” through the run, looking for the last write to that value. We can see that the last write was at step 3,282, by teller 2 (thread 141) on line 41.
But wait, 300 + 10 is 310. That write is fine! 🤔
The last write is rarely the bug. The money went missing earlier, when a teller wrote a value it had read much earlier. We need to augment blame with the reads too, to see that.
Who read it?
--reads lists every read and write of the value, back to the start of the process. Here are the rows around where it goes wrong:
$rewind blame 240115d5 --at 3291 balance --reads step thread access value where
...
3244 140 bank read 110 bank.c:36 teller long seen = balance;balance
3248 141 bank read 110 bank.c:36 teller long seen = balance;balance
3250 140 bank write 120 bank.c:41 teller balance = seen + amount;balance
3250 140 bank read 120 bank.c:36 teller long seen = balance;balance
...
3257 140 bank write 190 bank.c:41 teller balance = seen + amount;balance
3257 140 bank read 190 bank.c:36 teller long seen = balance;balance
3258 140 bank write 200 bank.c:41 teller balance = seen + amount;balance
3263 141 bank write 120 bank.c:41 teller balance = seen + amount;balance
...
searched back to step 3210, 1 keyframe window, 40 writes, 41 reads, 1.8s
Reading the chronology, we can see that teller 2 read the balance at step 3,248, and then teller 1 made nine deposits, taking the balance from 110 to 200. Then at step 3,263 teller 2 wrote its stale value of 120, overwriting the balance and losing the nine deposits (90). 💣
In this example, the bug is obvious, but in a real program it can be hard to find. The --reads option shows you the whole history of a value, and you can often see where it went wrong without ever setting a breakpoint. You can even see the bug in the plot of the balance over time:
The example is simple and the fix is obvious: a lock around the read and write. In a real program, the bug can be subtle and the fix complex. Seeing the history of a value, and who last wrote it, can be invaluable in tracking down the root cause.
In the app
The Rewind app gives the same information but in a more interactive way. The source panel underlines every value that blame can watch:
You can click on the value to see who wrote it, and then click Show reads too to see the whole history of that value.
Show reads too draws every access, one lane per thread. Teller 2’s lone read sits in the middle of teller 1’s deposits, and that one dot is the bug. 🙌
gdb, backwards
If you would rather drive, rewind gdb can go backwards too by setting a watchpoint and reverse-continue. Here it is forked at step 3,264, just after teller 2’s stale write:
$rewind gdb 240115d5 3264
(gdb) watch balance
Hardware watchpoint 1: balance
(gdb) reverse-continue
Thread 3 hit Hardware watchpoint 1: balance
Old value = 120
New value = 200
0x000056055a0ec50d in deposit (teller=2, amount=10) at bank.c:41
41 balance = seen + amount;
You can navigate the stack, inspect variables, and step backwards with reverse-step and reverse-next.
Rewinding by fast-forwarding
How does this all work? How do you run a VM backwards?
You don’t. 😅
Rewind replays are completely deterministic: the same run produces the same result every time. Turns out that a simpler way to go backwards is to run forwards again, but stop one instruction sooner than last time. That is all blame and reverse-continue do.
Rewind keeps a checkpoint of the machine at the start of a step. It rewinds to that checkpoint and then runs forward back to the step you want to inspect making note of every read and write along the way. If no reads or writes are found, it rewinds to the previous checkpoint and runs forward again. It keeps doing this until it finds the last read or write before the step you want to inspect.3
Deterministic replay is what makes this work, and it keeps the implementation simple: going back is just going forward again from earlier.
I’ve been having a lot of fun debugging my own programs this way. It’s a bit like time travel without the paradoxes. You can see the whole history of a value, and who wrote it, without setting a breakpoint and restarting the program.
It’s git blame for your program’s memory. 🔍
Tools like rr and Undo record a process and let you run its replay backwards. Rewind records the whole machine, the kernel included, so the same inputs make the same run every time. ↩
The expression can be a variable, a pointer dereference, or a struct field. ↩
A step can be millions of instructions, so this can take a little bit. ↩
That setup has one limitation: the SSH server in the initrd is only
reachable on my local network. If my file server reboots while I’m
away, for a power cut or a kernel update, it just sits there waiting
for passphrases until I get home. I could forward a port on my router,
but I really don’t want an SSH server exposed to the internet, and
certainly not one running in an initrd.
Here is something to think about: bugs are not rare, but rather the orderings of events that trigger them are. What do I mean by this?
Let’s start with a simple story. When I worked at AWS on RDS (Relational Database Service), we built the control plane for the service using workflows, of course using SWF (Simple Workflow). The workflows would execute a series of steps to create, modify or delete a database instance. Every so often we’d see something that looked impossible: a workflow that seemed to run its steps out of order.
What we actually observed was a pause. A worker would pick up a step and then stop for an unexpectedly long time. While paused it stopped heartbeating, so SWF decided it was dead and reassigned the step to another worker. The new worker finished the step and the workflow moved on. Then the first worker woke up. As far as it could tell no time had passed, so it carried on with the step it was holding, causing havoc in its wake.
We suddenly realized that we were not adequately testing all the possible schedules of events. The workflow code was correct, but the schedule that triggered the bug was not one we had ever seen in our tests. It was a rare schedule, but it was not a rare bug. So we began adding idempotency tokens to every step and making sure that every step could be run multiple times without breaking anything. It was a lot of work, but it made the system much more robust.
What’s the purpose of this story?
I am building Rewind VM, a deterministic VM. It helps find bugs in software primarily by running the same code under many different schedules.1 The mere act of shuffling the schedule has found many bugs thus far.
The software under test is not even a distributed system, such as the workflow example above, and yet many of the bugs are still schedule-dependent. No crazy Jepsen test suite needed. How can this be? All these projects have tests that validate the code on every change. Why does shuffling the schedule find so many bugs that all those tests never did?
The bugs aren’t rare; the schedules your tests run are. An idle, fast machine runs the same handful of orderings nearly every time. A test passes because the order never changes, and the code may only ever have handled that one order.
It takes different schedules or unforeseen long pauses, similar to the workflow story above, to trigger these bugs. The bugs are not rare, but the schedules that trigger them are. How rare are they?
The smallest race I know is counter++ from two threads.
Two threads run increment once each. Each thread’s three steps execute in order, but the two threads can interleave. An ordering is a choice of which 3 of the 6 slots belong to thread A, so there are of them.
We can visualize the 20 choices as paths on a grid. A step right is a step of thread A, a step down is a step of thread B, and every path from the top-left corner to the bottom-right one is one ordering.
The shaded square holds the four points where both threads have loaded the counter and neither has stored it. Any path that enters it ends with the counter at 1, because the second writer stores the stale original value.
Only the two paths along the edges provide the “correct result” of 2, A entirely before B or B entirely before A. That is 18 of 20 orderings that lose an update. If every ordering were equally likely, this race would fire in 9 runs out of 10. 😱
What does this look like on a real machine?
Let’s build a small program that runs the two threads and records the order of their steps. The program is a bit more complicated than the simple counter++ above, because it has to record the order of the steps. It also has to be careful not to introduce any new races in the recording itself. The program leverages Rewind’s rewind_point() to give Rewind VM a place to switch threads.2
race.c
/*
* Two threads each add one to a shared counter in three steps: load the
* counter, add one, store it back. No lock, so a thread that runs between
* the other's load and store writes a stale value over it.
*
* Each step first takes the next slot of a shared atomic sequence and
* writes its thread's letter there, so the program prints the order the
* six steps ran in, such as AABABB, and the final counter.
*
* rewind_point() between the steps gives Rewind VM a place to switch
* threads. main() calls it once before the threads start, so the one
* failed open it makes outside Rewind happens there; on the host the
* points inside the threads are a load and a branch.
*
* Built with -DSTART_BARRIER, both threads wait on a barrier before the
* first step, so they start as close together as the host allows.
*
* The exit status encodes the outcome so `rewind check` reports it
* without reading output: ordering index (0..19) * 2 + (1 if an update
* was lost).
*/#include<pthread.h>
#include<stdatomic.h>
#include<stdio.h>
#include<string.h>#include"rewind.h"enum{THREADS=2,STEPS=3,MARKS=THREADS*STEPS};staticvolatilelongcounter;staticatomic_intnext_mark;staticcharorder[MARKS+1];#ifdef START_BARRIER
staticpthread_barrier_tstart;#endif
/* Record that thread `who` is taking its next step. */staticvoidmark(charwho){order[atomic_fetch_add(&next_mark,1)]=who;}staticvoid*increment(void*arg){charwho=*(constchar*)arg;#ifdef START_BARRIER
pthread_barrier_wait(&start);#endif
mark(who);longseen=counter;/* load */rewind_point();mark(who);seen=seen+1;/* add */rewind_point();mark(who);counter=seen;/* store */returnNULL;}/* The index of `s` among the 20 orderings of AAABBB, in sorted order. */staticintordering_index(constchar*s){intindex=0;for(inta=0;a<64;a++){charcandidate[MARKS+1];intas=0;for(inti=0;i<MARKS;i++){candidate[i]=(a>>(MARKS-1-i))&1?'B':'A';as+=candidate[i]=='A';}candidate[MARKS]='\0';if(as!=STEPS){continue;}if(strcmp(candidate,s)==0){returnindex;}index++;}return-1;}intmain(void){staticconstcharnames[THREADS]={'A','B'};pthread_tthreads[THREADS];/* Open /dev/rewind, or find it missing, before any thread runs. */rewind_point();#ifdef START_BARRIER
pthread_barrier_init(&start,NULL,THREADS);#endif
for(inti=0;i<THREADS;i++){pthread_create(&threads[i],NULL,increment,(void*)&names[i]);}for(inti=0;i<THREADS;i++){pthread_join(threads[i],NULL);}intlost=counter!=THREADS;printf("%s %ld\n",order,counter);returnordering_index(order)*2+lost;}
I ran both builds, with and without the barrier, 10,000 times each on my laptop, a Ryzen 7 7840U with 16 idle hardware threads.
Across 20,000 runs the idle laptop ran 5 of the 20 orderings and lost an update 4 times.
Interestingly, the barrier was supposed to make them collide. Instead it flipped the order such that 9,957 runs were BBBAAA.
A busy machine is a little different. With stress-ng --cpu 16 keeping every hardware thread busy, the same two binaries ran 13 and 16 of the orderings, and lost an update in 32 and 66 of 10,000 runs. That’s still fewer than 1 run in 100 losing an update.
Rewind runs the guest on one virtual CPU and only switches threads at an exit, such as a system call (see dafuq is a deterministic VM?) or a rewind_point SDK call. This gives Rewind a chance to modify the schedule.
We can then run the same binary with Rewind to see how many of the 20 orderings it can reach.
$rewind check --epoch 1790985600 --root root --schedules 9999 \ --all --no-narrow -- /bin/race
...
schedule 9999: exited:0 354 steps run 9b248f72f742b07f
1492 of 9999 other schedules ended differently
Across 10,000 runs Rewind reached 15 of the 20 orderings and lost an update in 1,371 of them. With a barrier it reached all 20 orderings and lost an update in 2,997 of them.
We can observe that Rewind’s perturbations reach more orderings than the host, and that it loses an update more often, which helps us find the bug. The table below summarizes the results:
Where
Start
Orderings seen
Runs that lost an update
idle laptop
create
2 of 20
0 of 10,000
idle laptop
barrier
5 of 20
4 of 10,000
busy laptop
create
13 of 20
32 of 10,000
busy laptop
barrier
16 of 20
66 of 10,000
Rewind
create
15 of 20
1,371 of 10,000
Rewind
barrier
20 of 20
2,997 of 10,000
Interleavings, though, are not the only way to trigger bugs. Long pauses are orderings too, and they can be even rarer than interleavings.
A long pause sits at the far edge of the grid. Thread A stops, and everything else takes hundreds of steps before A takes its next one. A path like that runs along one edge of the grid for a long time. A short perturbation hands the other side a few steps, so it rarely walks that far.
Rewind has knobs to make long pauses more likely. The --stall-max knob raises the maximum stall time, and the --stall-min knob lowers the minimum stall time. These settings can help explore even more unlikely schedules to discover bugs that only appear under extreme conditions.
It’s kind of surprising that with all the hype around property-based testing, fuzzing, and Jepsen, a simple deterministic VM that shuffles the schedule finds so many bugs.
Our hardware is so fast that we’ve become accustomed to thinking that the order of events is always the same. Adding a little randomness to the schedule can expose bugs that have been hiding in plain sight.
Bugs aren’t rare, but the schedules that trigger them are.
I say schedule rather than thread interleaving on purpose. Most of the bugs on that page are races between processes, or between a process and a signal. Only a few are between two threads of one program. ↩
The program also has a version that uses a barrier so the threads collide on purpose, which should make the race even more likely. ↩
What is time inside a machine you want to replay? 🧘
When building Rewind, a deterministic VM, you come face-to-face with the idea of how to represent time very quickly. You need a way to measure time inside the guest so that on subsequent replays, the guest sees the same time and makes the same decisions. Time is the ultimate variable.
You can’t simply record the wall-clock time of the host because time spent between two interception points depends on things outside the guest, like host load, CPU frequency, caches and other processes. Therefore the same guest work can take a different amount of time on the host.
In dafuq is a deterministic VM? I explained how the clock inside Rewind VM moves 5 microseconds per step. More specifically, that clock, exit time, moves only when the guest exits such as from a syscall. It treats everything the program does between two exits as instant. Therefore a program that is CPU bound such as doing nothing but math for a full second between two system calls, sees only 5µs go by. 🤦🏻♂️
Rewind has a second clock mode as well, counter time, that tries to account for the work. The clock advances one nanosecond for every conditional branch the guest retired.1
Still confused about what I mean by “free” and “branches”? Let’s look at a simple example to distinguish between the two clocks.
The counter time tries to account for the work whereas the exit time only advanced the clock on exits.2
Why branches, though?
What is time in a replayed machine?
We already understand that we cannot rely on the wall-clock time of the host. We need something to measure that is the same for every run of the same program so that we can equate it to time spent.
What is the same on every run?
The guest’s instruction stream! The CPU is a deterministic machine: the same input, the same registers, the same memory, and the same instructions produce the same next state.
We can measure time by measuring progress through the instruction stream. 💡
Turns out that CPU manufacturers even ship a hardware counter for exactly that. Is it reliable? Let’s see. 🧐
Let’s use this simple program: count down from a billion.
The assembly equivalent contains a mov, a billiondec+jnz (conditional branch) pairs, then three instructions to exit for a total of 2,000,000,004 instructions.
Let’s run it on the CPU twice and count the instructions and conditional branches with perf stat:
The same program and input gives the same conditional branch count, but the instruction count is off by a thousand or so. Why?
Although this loop is CPU bound and only decrements a register, it is still not isolated from the effects of the outside world. Timers tick, network packets arrive, other cores send inter-processor interrupts (IPIs). The program can’t see any of that, but the instruction counter we are probing can.
I pinned the loop to a single CPU and counted how many interrupts that CPU took during each run, from /proc/interrupts.
The dashed line is one extra count per interrupt, and the instruction counter is almost perfectly on it.3
The conditional branch counter on the other hand, stays at zero no matter how many interrupts land.
Interrupts from the outside-world are not the only thing that can skew the instruction count. The program can also page fault, which is an interrupt too. The instruction counter sees the kernel’s detour to handle the fault, but the program does not.
Tip
Out of the box, AMD Zen also overcounts conditional branches, a few in tens of millions, from a speculation optimization known as SpecLockMap. The fix is to set a particular bit in the PMU MSR, which Rewind does automatically as does rr#2034.
So, what time is it?
In order to rewind history, we need a measurement of time that is reliable and deterministic. Our traditional wall-clock time is unreliable due to the effects of the outside world but we do have a reliable measurement of progress through the instruction stream: the conditional branch counter.
Using the conditional branch counter as a proxy for time turns out to be a relatively decent approximation.
Clock
Time inside the VM
Time on the host
Exit time
2.1 s
15.7 s
Counter time
11.7 s
14.2 s
Why do we care about having a “realistic” representation of time?
Plenty of programs read the clock and make decisions with it, so the guest’s clock has to be at least somewhat realistic. Under exit time, computing is “free”. A test that checks some work “finishes within 1 s” always passes. If the bug you’re chasing is a timeout, exit time will never reproduce it. 🙃
Races get skewed too with an unrealistic clock. With exit time, a whole burst of work lands in the same instant, which crowds the threads together, so a race can fire far more often in the VM than it ever would on real hardware.
The closer we can emulate the real world, the more likely we are to reproduce a bug that only happens in the real world. Counter time is a better approximation of the real world than exit time, and it is deterministic, so it is the default clock in Rewind.
Some say time is an illusion. I say it’s a jnz counter.
This is the same approach popularized by the rr debugger. The rr paper calls it deterministic time. ↩
The 5µs was my guess at a reasonable cost of a system call and context switch on current hardware. The 1ns is roughly what a conditional branch costs on a current core. ↩
The fit is 0.94 rather than 1 because /proc/interrupts also catches the interrupts that land while perf and taskset start up and tear down, before and after the loop runs. ↩
I have been stress testing Rewind VM, a deterministic VM, to work through the kinks, bugs and dog-fooding the user-experience. Even having developed it myself, I continue to be wild-eye amazed at the magic of what it can do.
Despite the magic, the ease of claiming to have a bug “reproduced deterministically”, and the ease of narrowing it down to a single step, the hard part is still reading the code and understanding why it failed. Rewind can tell you what went wrong, but it cannot read the code.
This is a particular area that is ripe for AI assistance. Agents can already read the code and often find bugs. Unsurprisingly, when given a wealth of reliable data about what went wrong, they can pinpoint the bug in a way that is much more efficient than reading the code alone. The combination of deterministic runs and AI agents is incredibly powerful. 🪄
Finding the bugs in Rewind is easy. rewind check replays a test, script, or binary under many different thread schedules until one fails, then narrows the failure down to the single step. That leaves you, though, with a step number and potentially a large codebase, one you are unfamiliar with. The hard part is reading the code and understanding why it failed.
Rewind can tell you what went wrong, but it cannot read the code for you. Rewind does however give you, or an agent, a lot of information about what went wrong. I pointed Rewind VM at a cornicopia of tools, and unsurprisingly, it found bugs…many bugs. The best part is that it found them in a way that is reproducible and debuggable, which has led to the agents also easily providing the fixes as well.1
This is a small example of a bug that Rewind found in git, and how I used Rewind to find the bug and the line of code that caused it. The bug is in git notes, which attaches a note to a commit without changing the commit. The bug is that two notes, on two different commits, at the same time, can lose one of the notes.2
The bug
git notes attaches a note to a commit without changing the commit.
We can start with an idea for a simple test3: create two notes, on two different commits, at the same time concurrently.
git notes add -m"note 1" HEAD~0 &
git notes add -m"note 2" HEAD~1 &
wait# both commands exited 0, so both notes should be there
git notes show HEAD~0 && git notes show HEAD~1
$rewind check --all--schedules 32 --property exit-zero .#notes2
schedule 1: exited:1 3167 steps run e5e5a1ecd0195f8f violates exit-zero
schedule 2: exited:1 3312 steps run ea6889e56564e374 violates exit-zero
...
15 of 32 other schedules violated a property
step 2682 decides it: a request to switch threads there makes the run violate exit-zero
When executed by Rewind, fifteen of thirty-two schedules lose a git-note, yet every git notes add still exits successfully.4
Now what?
Ask the runs, not the code
A run in Rewind is a full trace of the build: every process, every file it wrote, and any file’s contents at any step, that you replay to any point in time. That is a lot of data. Rewind does make it a little simpler to comb through the data though that help narrow the culprit.
None of those three commands knows anything about git, locks or races. They work on any program.
What ended differently?
rewind diff --outputs compares the files the two runs left behind. This is like diffoscope but on steroids 💉: it can compare any two runs, and it can compare the files at any step in the run, not just the final outputs.5
$rewind diff --outputs 94c59fdf987c4944 ad0de5aec5a0be2d
3 of the 30 files the runs left behind differ:
/build/r/.git/logs/refs/notes/commits: 36 of 465 bytes differ, first at byte 351
/build/r/.git/refs/notes/commits: 36 of 41 bytes differ, first at byte 0
/nix/store/014fz1lj7hmk5h3rzcaw0w4576md3bg9-git-notes2: only in the right run
Our clue is that .git/refs/notes/commits is the ref that points at the latest notes commit, and it points at different commits in the two runs.
Who wrote it, and what did it read?
rewind blame takes two runs and a file:
$rewind blame 94c59fdf987c4944 ad0de5aec5a0be2d /build/r/.git/refs/notes/commits
commits differs at byte 0. git notes (pid 56) wrote that byte at step
2,751 in run 94c59fdf and at step 2,717 in run ad0de5ae.
...
Likely cause: git notes (pid 56) read /build/r/.git/refs/notes/commits
before git notes (pid 55) changed it at step 2,721 in run 94c59fdf,
and after that change in run ad0de5ae. It read an older version of
the file in run 94c59fdf.
In this example, Rewind has given us pretty close to the smoking gun. The second git notes add read the notes before the first one had saved its own, then saved its version over the top: a read-modify-write race.
We can visualize this exact step in the Rewind GUI at the deciding step: both git notes add processes are alive (top box), and the first is halfway through saving, with its lock file written but not yet renamed into place (bottom box).
Which line wrote it?
If we have access to debug symbols, which Nixpkgs provides, rewind where shows where in git’s own code a process was at a step. Here is pid 56 when it wrote the ref:
$rewind where 94c59fdf987c4944 2754 --pid 56 --frames 8
process 56 (git), thread 56, at step 2754
#1 rename_tempfile (tempfile.c:347)
called from #2 commit_lock_file_to (/build/source/lockfile.h:364)
called from #3 commit_lock_file (lockfile.c:358)
called from #4 commit_ref (refs/files-backend.c:1889)
called from #5 files_transaction_finish (refs/files-backend.c:3381)
called from #6 ref_transaction_commit (refs.c:2806)
called from #7 refs_update_ref (refs.c:1592)
called from #8 commit_notes (notes-utils.c:64)
We can then look at the code at a very specific line, and try to understand why it failed.
In this case, notes-utils.c:64 updates the ref without checking that it still points where it did when the command loaded the notes with a lock.
Three questions, three commands, and I read one line of git. 🤓
Who reads all of this?
The git notes failure is 2,936 steps and 1,937 events in one run, and rewind check made 33 runs. Going through one run is a lot of work, and going through all thirty-three is unrealistic.
Recently, a friend told me AI has been really useful for parsing the CAN bus of cars. The CAN bus is a firehose of messages from the car from every sensor, every button, every switch, and every light. LLMs have made managing the firehose of data easier.
I see the same emergence in Rewind. The run is also a firehose of events, and similarly, LLMs can help parse the firehose of events and find the bugs. Telling an LLM to investigate a bug with Rewind has been very effective. Narrowing the bug down to a single step and source lines, is especially helpful for an LLM as it keeps the context small and focused. At that point, the LLM can read the code and understand what went wrong, and very likely suggest a fix.
LLMs have a lot of stochasticity built into them. I have found that pairing them with more deterministic technologies such as Nix and Rewind makes them more effective. I’m very optimistic about the
leveraging the combination of deterministic runs and LLMs to find and fix bugs in large codebases.
LLMs induce many of these bugs but now they can also fix them. 🙃
This test demonstrates the race condition in git notes when adding notes concurrently. We can easily build this as a Nix derivation using runCommand. ↩
On a normal Linux machine, 25 of 30 runs lose one too, so this is not a Rewind-onlybug. ↩
I have a lengthier post about how Rewind can help make your build bit-for-bit reproducible. ↩
Since I started writing about Rewind VM, the question I get most from friends is not “does it work?” but “how does it actually work?” 🤔
D’uh! It is a virtual machine that only gets interrupted when it asks to be.
That seems to not have helped much, so let’s go deeper.
We will follow a tiny C program through the machine and, at each step, look at where non-determinism would have crept in and what Rewind does about it.
CPUs must be deterministic. If they were not, we would have a very bad time trusting them to do anything.
Give a CPU the same registers, the same memory and the same instructions, and it computes the same result.
What does change? Why are machines not deterministic?
They are not closed systems. They interact with the outside world and that interaction is not deterministic. A timer interrupt can land at any instruction or a disk read can complete at any time.
Aside:
Computers can’t actually make random numbers. A deterministic machine can only fake it with pseudo-randomness: run the same algorithm from the same seed and you get the same numbers back. The real stuff has to come from the physical world. My favorite example is how Cloudflare keeps a wall of 100 lava lamps in its San Francisco office with a camera pointed at it, feeding its encryption keys.
If we could capture all external influences, we could replay the external world and get the same run again. That is what Rewind does.
Every source from the outside world is either removed or replaced with a value derived from a stored seed. Time, for instance, is a clock managed by Rewind. Interrupts arrive only at points we choose. ⏱️
One more outside influence is easy to miss: other CPUs. On two cores, which thread wins a race comes down to cache misses and pipeline stalls, so Rewind provides a single virtual CPU and the threads take turns on it.
A step is a VM exit
To control the outside world, Rewind needs moments where the software stops and Rewind can step in. At those moments it writes down what just happened, hands over the current time, or delivers an interrupt. So how do you stop the software at the same place on every run?
One answer is to make the hardware do it. CPUs have performance counters that can interrupt after a set number of instructions.
Unfortunately, the interrupt may arrive a few instructions late, and the amount varies.1
Rewind uses a cooperative approach: let the software tell us when something happens!
Rewind runs the guest under KVM, the hypervisor built into Linux. The guest’s code runs directly on the real CPU until it touches a device. The CPU then stops the guest and hands control to the program running the VM, Rewind’s monitor (rewind-vmm). That hand-off is a VM exit.
Rewind patches the guest kernel so that whenever it needs something only the outside world has, such as the time, a timer, or “I have nothing to do”, it makes an exit and asks the monitor. Reporting what happened, like a process starting or a line of output, is an exit too.
Each exit the guest makes is called a step, and they are numbered starting from boot.
If we assume the guest is deterministic up to step N, step N happens at the same instruction on every run.
The monitor’s loop, sketched in Python:
step,clock,deadline=0,0,NonewhileTrue:# The guest runs natively until it exits.
exit=vcpu.run()# The host's own business: not a step, and nothing is sent.
ifexit.reason==HOST_INTERRUPT:continue# An exit the guest made. Time moves only here.
step+=1clock+=QUANTUM# Read the clock, arm a timer, log an event...
deadline=handle(exit,step)# Interrupts go in only here, with the guest stopped.
ifdeadlineisnotNoneandclock>=deadline:vcpu.inject(TIMER_INTERRUPT)deadline=None
This is true on the first run too. Nothing gets recorded, and a replay just runs the same inputs again.
Three pieces make this work, and your program doesn’t need to know about any of them.
A patched Linux kernel. The guest kernel is the piece that cooperates. A small patch teaches it to take its clock, its timer and its idle loop from the monitor instead of from hardware, and to report what processes do: exec, exit, output, files written. The monitor also hides the CPU features that would leak the outside world in, such as the hardware cycle counter and the random number instruction, so the kernel never uses them.
rewind-init. The special PID 1 is a small program that mounts the input image (a Nix closure or a root filesystem), runs the command, reports its exit status and powers the machine off. The image is mapped straight into guest memory, so reading a file is reading memory, and there is no disk to finish a read at a random moment.
rewind-vmm. The monitor owns time, decides when interrupts go in, and keeps the trace of everything the kernel reports.
The life of a system call
Here is the program. It reads the clock, draws a random number, prints both with the address of a stack variable, sleeps for a second, then reads the clock again.
On my laptop every run prints something new. In Rewind, every run prints the same thing, down to the nanosecond, until you change the seed:
$rewind run --root root -- /bin/hello
time=1792886400.001006990 random=166963147 stack=0x7fff2bad5e4c
time=1792886401.001132684
rewind: run 85a03383f7d917d9 exited:0 after 432 steps, 1.002s virtual, 1.139s wall (poweroff)
$rewind run --root root -- /bin/hello
time=1792886400.001006990 random=166963147 stack=0x7fff2bad5e4c
time=1792886401.001132684
rewind: run 85a03383f7d917d9 exited:0 after 432 steps, 1.002s virtual, 0.394s wall (poweroff)
# a different seed is a different input, so a different run
$rewind run --root root --seed 1 -- /bin/hello
time=1792886400.001006990 random=2117056732 stack=0x7ffdd58e5bdc
time=1792886401.001132680
rewind: run 59c7da84895c210a exited:0 after 432 steps, 1.002s virtual, 0.848s wall (poweroff)
Same inputs, same run id, same 432 steps. Oh, and the program slept for a second, yet the whole VM finished in 0.39 seconds. 🤓
Normally, reading the time never enters the kernel: a bit of code in every process reads a hardware counter directly. Rewind hides that counter, so the read goes to the kernel, and the kernel asks the monitor.
Rewind hides the CPU’s random number instruction, so the only thing
available to the guest kernel is the seed Rewind passes at boot. The kernel’s random number generator is seeded with that value, so every run of the same program with the same seed gets the same random numbers.
Most system calls never leave the guest. The few that need the outside world make an exit, and the monitor writes down what happened. The guest kernel also reports when it is idle, so the monitor can jump its clock to the next timer interrupt.2
Control those few doors and the guest is deterministic: the outside world shows up at the same step on every run.
So, dafuq is a deterministic VM? Like I said at the start, it’s a VM that only gets interrupted when it asks to be. Hopefully that makes a bit more sense now. 😅
Intel’s counter is good enough that you can single-step the rest of the way to the exact instruction. I have an AMD laptop. 🙃 ↩
sleep(N) costs no real time. The monitor jumps its clock straight to the deadline and delivers the timer interrupt. ↩
I don't know if you've seen this, but a CA just got popped. Their keys got leaked, which means the industry as a whole now has some pretty major problems. It was revealed two hours ago.
Now you're probably wondering why I'm writing up this blog post. It's simple. This is perhaps one of the easiest security patches I've ever done, and I've discovered a few new tricks. First, understand that fixing this with ease without Nix is almost impossible. Tens of millions of dollars (if not more) in productivity are being lost worldwide right now as everyone tries to patch their transitive dependencies.
Meanwhile, because I've used Nix, I can patch the planet, since the ideas behind the blog post below extend into security as well.
So the problem here is the transitive dependencies. It's easy to patch one thing, but the transitive dependencies are the problem, and this is where Nix shines: one fix fixes the transitive dependencies automatically.
One patch fixes the entire fleet and its transitive dependencies. Patch, commit, and autodeploy your fleet 🍻
the new trick
Alright, I promised a new trick. Here's the trick.
You can prompt an agent to update the AGENTS.MD to automatically back out these patches, let's say in five days from now, just by using the AGENTS.MD as a reminder 😎
So it was one simple prompt to identify if I was affected, which turned into a plan, which then automatically fixed it, and now, in a couple of days, it will reassess the situation, give time for the ecosystem and dust to settle, and then automatically back it out once all the upstream transitive dependencies have been resolved.
Cool, huh?
## Temporary reminder: eMudhra root blacklist (from 2026-10-22)

On or after 2026-10-22, check whether the `nixos-26.05` channel contains nixpkgs
commit `7816d39` (the backported `security/ca.nix` distrust of the eMudhra roots), e.g.
`nix eval --raw --refresh --impure --expr '(builtins.getFlake "github:NixOS/nixpkgs/nixos-26.05").rev'`
then `git merge-base --is-ancestor`. If it does not, check again two days later.
Once it does, back out the fleet-wide workaround: update the `nixpkgs` pin to include
it, delete `nix/domains/system/public-trust.nix` (contract `fleet-distrust-emudhra-roots`)
and its imports in `nix/domains/system/catalog.nix`,
`nix/domains/artifacts/guest/configuration.nix` and the `host-kexec` modules in
`flake.nix`, and remove the eMudhra paragraph from
`marshall/priv/hldd/12-configuration.md`. Then verify that the built host and guest
bundles still lack the four roots, and delete this section. Keep Marshall's
system-store TLS defaults (`runtime-postgres-system-trust`, `mail-smtp-system-trust`)
and the `rustls-webpki` update; they are not part of the workaround.
I can't stress this enough. If you build something, you own it, including all the dependencies you rely on. We're entering weird times where cyber offensive models will be continuously on the attack.
The game has changed. To defend, you need more inferencing capability than the attacker, and you also need to respond rapidly.
This is by far the easiest security patch I've ever done, and the best part is I won't carry this tech debt for long because an agent will automatically back it out in a couple of days.
For about 10 years I’ve worked at the same company, and for about 9 of
those years I’ve been running NixOS on my work
machine with a setup that I’ve built and tuned exactly the way I want
it.
Then corporate security decided that all devices needed to be
managed. That’s a perfectly reasonable requirement from their side,
but it’s not something that works with a custom NixOS setup. So I got
handed a MacBook Pro.